🤝 Top Collaborators
🤓 Latest Submissions
Local-First Batch Agent
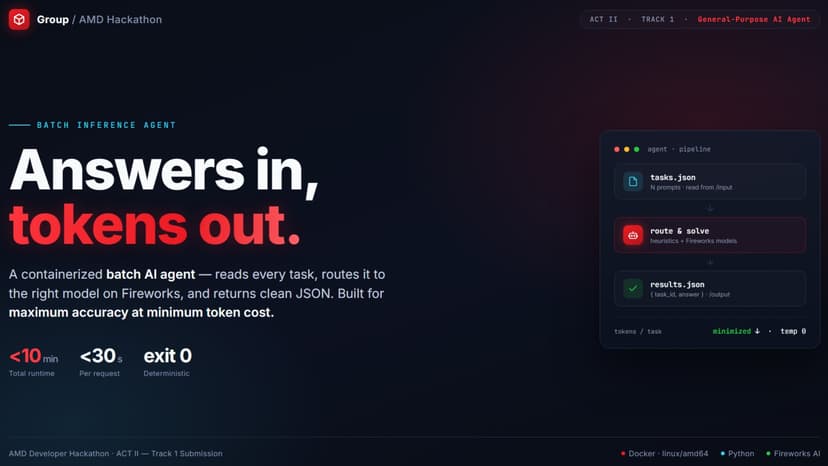
Our Track 1 submission is a batch AI agent engineered for the competition's scoring rule: clear the accuracy gate, then win on fewest tokens. Since only tokens routed through the Fireworks proxy are counted, we make most tasks free. The agent is local-first: a bundled Qwen2.5-3B-Instruct model (4-bit GGUF) runs on CPU via llama.cpp and answers each of the eight task categories — factual, math, sentiment, summarization, NER, code debugging, logical reasoning, and code generation — at zero Fireworks tokens. A zero-token heuristic router assigns each prompt a category, prompt template, output cap, and verifier. Conservative per-category verifiers keep well-formed local answers and escalate only clear failures to a Fireworks model as a safety net. On our 40-task benchmark the local model alone reaches 90% accuracy. Everything ships as one self-contained, publicly pullable linux/amd64 Docker image.
13 Jul 2026
