
Muhammad Abdullah Butt@abdullahbutt357960727
🤝 Top Collaborators

🤓 Latest Submissions
clawback
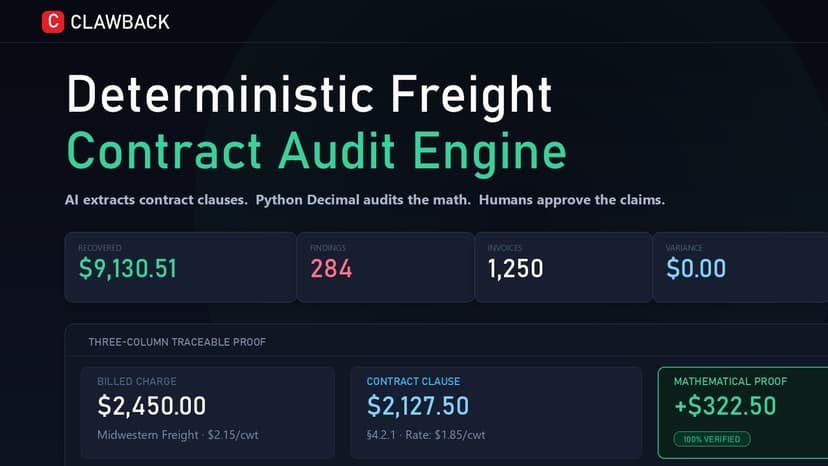
The Problem Shippers pay carrier invoices with thousands of charges, and nobody has time to check each one against the negotiated contract. Audit vendors report that freight audits recover about 3 to 7 percent of freight spend, and carriers often allow only a short dispute window, commonly around 15 days for parcel. Outsourced audit firms commonly take 20 to 50 percent of what they recover. These figures come from vendor sources and are indicative only. Why This is a Commerce Track Project Most commerce tools chase top-line revenue growth. Clawback protects margin from the cost side. In commercial logistics and supply chain operations, freight spend represents 8 to 15 percent of total cost of goods sold (COGS). A dollar recovered from an overcharge drops directly to pre-tax net margin. How AMD is Used Model & Host: The model that reads contracts and normalizes messy invoice charge descriptions is google/gemma-2-9b-it, hosted on AMD Developer Cloud / AMD Token Factory infrastructure (notebooks.amd.com). Replay Mode: When offline or if API quotas are exhausted, a deterministic replay mode serves recorded outputs from real AMD calls, visibly labeled with a persistent REPLAY badge. Workload Concurrency: Utilizes k=3 parallel self-consistency consensus extraction and batch charge-description normalization, fully utilizing AMD ROCm GPU concurrency. Measured Results (Synthetic Benchmark) Source: benchmark/results.json (Mode: replay / baseline; Run Date: October 16, 2026). Accuracy: Audit Recall: 100.00% (284 of 284 planted errors detected) Audit Precision: 100.00% (0 false positives) True Positives: 284 | False Positives: 0 | False Negatives: 0 Planted Ground Truth: $9,130.51 USD Recovered Overcharges: $9,130.51 USD Dollar Variance: $0.00 (0.00%) Note: These results prove the pipeline and deterministic arithmetic engine work as designed on synthetic benchmark data. They are not evidence of real-world carrier recovery rates.
18 Oct 2026
TokenForge Final
TokenForge is a production-grade Hybrid Routing Engine and AI Cost Governor engineered to solve the enterprise crisis of escalating cloud LLM inference fees and latency overhead. Built in strict compliance with the Track 1 headless container contract, the system automatically processes multi-domain tasks by ingestibing prompts from /input/tasks.json and generating schemas perfectly matching the /output/results.json specification. The core architecture introduces a multi-tier optimization paradigm: Tier 0 (Deterministic Local Solvers): To achieve true token elimination, incoming prompts enter a thread-safe ResponseCache before hitting an 8-Category Regex Classifier. Mathematical, algebraic, text-extraction, and sentiment analysis tasks are intercepted and processed natively using local SymPy, spaCy, and VADER engines. This guarantees 100% precision and records exactly $0.00 in marginal API costs, operating entirely within the zero-token ruleset. Tier 1/2 (Cloud Escalation): When a prompt requires deep reasoning or code generation, the engine dynamically escalates execution via the official Fireworks AI proxy. It actively respects environment runtime flags like ALLOWED_MODELS and enforces category-specific token caps. It prioritizes open-weight Google Gemma models (gemma2-9b-it) to optimize cloud tokens, competing directly for the specialized Google Gemma Prize. Fully concurrent with an 8-worker parallel thread pool, TokenForge v2.0 executes complete task evaluation suites in less than one second under severe headless constraints. Packaged as a clean, multi-architecture linux/amd64 Docker image, it bridges algorithmic precision with absolute cost governance.
13 Jul 2026


