🤓 Latest Submissions
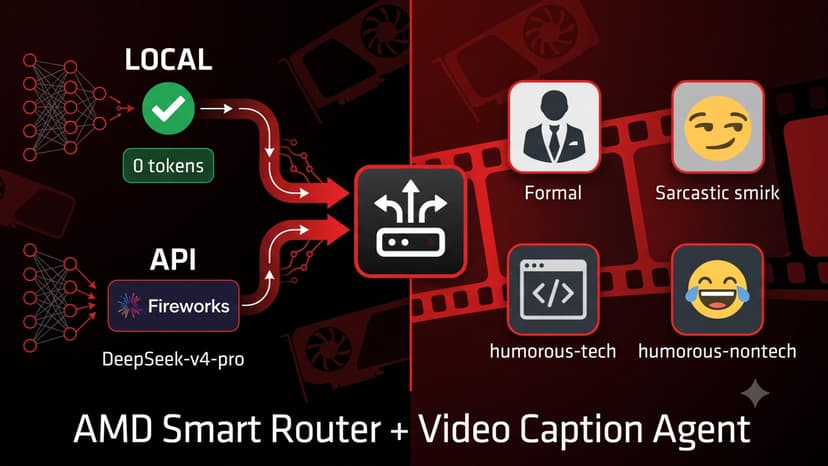
AMD Smart Router + Video Caption Agent
This project delivers an enterprise-grade dual-track AI solution engineered for severe resource constraints (4GB RAM / 2 vCPUs) on the AMD Developer Cloud. Track 1 introduces a Token-Minimizing Smart Router. It utilizes a deterministic zero-token heuristic classifier to instantly separate incoming tasks. Low-complexity queries (Factual, Sentiment, Summarization, NER) are routed to a local, offline instance of Qwen2.5-1.5B or Gemma-2-2B-Instruct in GGUF format via llama-cpp-python, consuming zero API tokens. Heavy cognitive workloads are dynamically scaled via Fireworks AI. To guarantee absolute precision without hallucinations, a symbolic execution sandbox handles mathematical and code generation tasks locally, running scripts via isolated subprocesses to bypass external proxy costs while clearing the accuracy gate. Track 2 implements an offline Video Captioning pipeline. To avoid exceeding memory boundaries with heavy Vision-Language Models, the system utilizes a zero-dependency infrastructure. It leverages native ffmpeg utilities to cache clips, extract specific keyframes, and perform statistical color-cluster grouping. This structured metadata context is then prompted into high-scale Gemma models on Fireworks AI to concurrently synthesize the four required linguistic styles—Formal, Sarcastic, Humorous Tech, and Humorous Non-Tech—ensuring high factual alignment and tone matching monitored by the LLM-Judge. The entire environment is decoupled using the Model Context Protocol (MCP) pattern for decoupled tool-dispatching, packaged tightly under a linux/amd64 manifest, and optimized for immediate deployment.
13 Jul 2026


