🤓 Latest Submissions
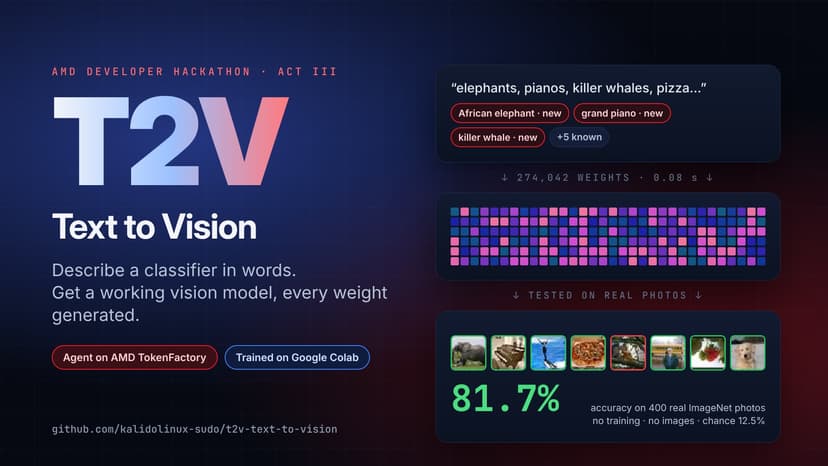
T2V · Text to Vision
T2V generates every weight of a working image classifier from a text description: no training run, no images of the new classes. How it works: an agent on AMD TokenFactory (DeepSeek-V4-Flash) understands the request in any language, describes what each class looks like, and reasons by analogy for classes it has never seen (killer whale ≈ submarine + giant panda). A parameter-diffusion generator, trained once in 72 minutes on a Google Colab T4 GPU, then writes all 274,042 weights of a ResNet-20 in 0.08 s. Results on ImageNet-1k: 86% of a fine-tuned network's accuracy on classes it never saw (63.6% vs 74.1%); with wrong class names it falls to chance, so the weights really come from the words. For commerce: type a new product line, get a 1 MB classifier for catalog tagging or visual search in seconds. Open source (MIT), one-click Colab demo.
18 Oct 2026

