🤓 Latest Submissions
Bob Secure Review
Teams ship more code now than they can read. AI wrote much of it, and AI reviews it — and that is where the trust breaks. An AI code reviewer that works and an AI reviewer that is broken produce the same output. So does a reviewer that never read the file at all. "No findings" is a verdict, not evidence: it looks identical whether the tool examined your code or merely said the words. Security teams already know this feeling — a scanner that reports clean after silently failing is worse than no scanner, because it retires the vigilance it did not earn. **Bob Secure Review** is a code reviewer that has to earn the right to say clean. Its users are the people who ship and review AI-written code: developers, security reviewers, and CI pipelines. They use it the way they use any reviewer — point it at a file or a repository and get findings with severity, category, and line ranges. What makes it different is a gate that runs before any clean result is allowed to count. Before Bob Secure Review may report that your code has no problems, it must first catch a vulnerability planted in a file it was not told about. And it must stay silent about that same rule on a copy of the file with the flaw removed. That second half matters more than the first. A reviewer that always shouts "vulnerable" passes a detection test and fails this one. Requiring silence on the clean twin forces the reviewer to discriminate — to show its output is a relation between the input and the code, not a script that fires regardless. There is a third state, and it is the point. When the reviewer cannot establish that discrimination — when the twin is too different, or too degenerate, to serve as a control — the verdict is withheld. Not clean. Not clean with a caveat. The system says it could not prove itself, and declines to answer. The margin that decides this is computed from the inputs rather than tuned: the twin is compared against a deterministically shuffled copy of the same source. There is no constant to calibrate and nothing to drift. The result is a reviewer whose all-clear is earned rather than asserted — and which reports a failure as a failure, including when the failure is its own.
27 Sep 2026
KCELL
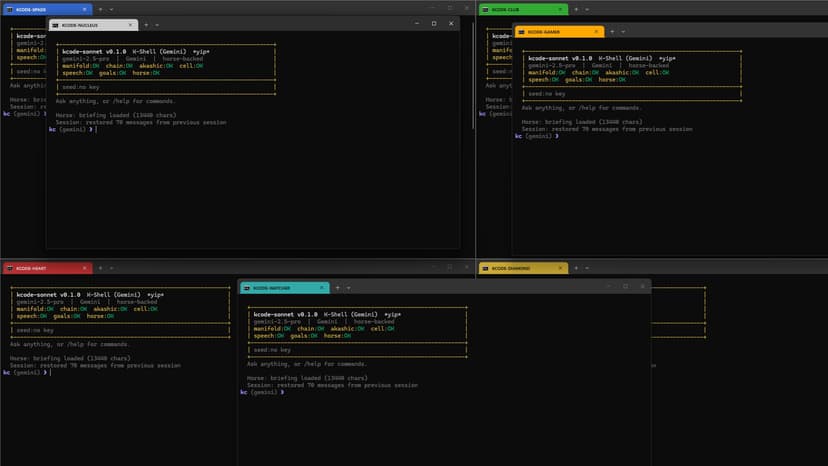
This agent orchestration can be fully audited every routing decision is retained in a bitcoin based golden ledger. The TERCOMs are based on terrain contour mapping in the tomahawk missile but repurposed to contour mapping. These can be used to feed data into the trading agent. Its a self reinforcing feed back loop the more data it can be fed the better the trading can get. It also does multilingual research in multi domains especially medical. I used it to find medical research on Kawasaki disease that can provide up to 20% increased likelihood of a positive outcome in affected children. The featherless inference engine powers our Cell's security tooling and can be orchestrated or dispatched to for any type of task. The idea is for the Gemini Cell to have specialized tooling in the hands of each agent that are more than the sum of its parts. We make this tool safe through attention layer routing. At its base is a semantic map with broad coverage of human experience including negative situations like Apophenia when a user gets too sucked into the conspiracy or pattern matching rabbit hole the model will be prompted to push back and explain how there can be correlation without causation, etc. This is an important feature with the rise of those sucked in by model behavior. We studied the early model Liza to analyze the risks of simulated conversation partners.
19 May 2026


