
Talal Khawaja@kmt9967
10
Events attended
6
Submissions made
Pakistan
6+ years of experience
About me
Hi, I’m Talal. I work on web/app development, automation, CRM systems, APIs, WordPress, GoHighLevel, Flutter, and digital marketing solutions. I enjoy building practical tools that solve real business problems, especially using AI, automation, dashboards, and workflow systems.
🤝 Top Collaborators


🔥 Own Projects
🤓 Latest Submissions

Dark Factory: One Message, Four Seats
We built a generic software factory, not an app. Four Claude Code seats run in one BAND Desktop room. The Architect plans and sends every handoff. The Implementer writes one scoped work item at a time. The Reviewer attacks each commit against every spec sentence. The Verifier runs a no-cache build and the organisers' checks in isolated mode (no network, 2 vCPU, 2 GiB) before releasing anything. The mandates say how each seat works, never what is built, and they pass the organisers' vocabulary scan for both tracks. The product lives only in the single task we posted to @architect at 20:32:50Z. Nothing else was posted. Result: all 4 pocketful stages were released in 6 h 14 m. On a fresh clone in isolated mode the shipped checks pass 147, 35, 6 and 5 (claimed stage 4). There were 28 seat commits, each under its own seat's name, and 87 seat messages. The Reviewer issued 3 rejections that changed the code, for example a hold that could be captured for 0 and an import that pushed the clock ahead. Estimated cost: $60.09 at list prices. We document what failed: two earlier attempts stalled (an MCP name clash, then a dropped reply). Both were fixed generically before the clean run. FACTORY.md is enough to stand the factory up, and room.json is the full room.
6 Oct 2026
LockSmith: IBM Bob fixes locking DB migrations
Problem. Database schema migrations ship through the same pull-request review as application code, but their risk is invisible in a diff. On PostgreSQL, a one-line CREATE INDEX holds a ShareLock that blocks every write for the whole index build; ALTER COLUMN … TYPE takes an AccessExclusiveLock and rewrites the table; a column rename is instant but breaks every running app instance that still uses the old name; and any heavy DDL without lock_timeout can queue behind one slow query and freeze all traffic behind it. Catching this requires lock-semantics expertise and table-size arithmetic most reviewers don't carry in their heads. Misses cause outages; the safe expand → backfill → contract rewrite costs a senior engineer hours per migration. Solution. LockSmith turns that review into a measured, automated gate — and hands the fix to IBM Bob. 1. Detect: 12 deterministic rules (LS001–LS012) over parsed SQL: non-concurrent indexes, NOT NULL adds, volatile defaults, type changes, SET NOT NULL, validated FK/CHECK constraints, renames/drops still referenced by application code, missing lock_timeout, CONCURRENTLY inside transactions, un-batched backfills. 2. Prove: every statement is replayed in an in-process PostgreSQL (PGlite). LockSmith reads pg_locks for the lock actually taken and compares relfilenode to detect table rewrites — evidence, not guesses. 3. Impact: declared production table sizes turn locks into "≈N seconds, ≈M writes blocked". 4. Rewrite with IBM Bob: the repo ships a custom Bob mode (Migration Surgeon), a Postgres lock reference Bob reads, and a lock-audit skill. Bob runs the gate, spawns one subagent per flagged migration in parallel, rewrites each into safe ordered files (concurrent indexes, NOT VALID + VALIDATE constraints, batched backfills, lock timeouts, dual-write app code for renames), then re-runs the gate on its own output. 5. Gate: the CLI exits non-zero while any critical finding remains, so CI blocks unsafe deploys. Target users: backend and platform engineers, reviewers and SREs at teams running PostgreSQL. They interact through the CLI in CI, the web report (per-migration lock evidence and impact), the paste-a-migration analyzer, and Bob IDE for the rewrite. Result on the demo repo (fictional e-commerce app, 8 pending migrations, orders = 42M rows): gate FAIL, risk 100 → after Bob's rewrite gate PASS, risk 0, with 6 dangerous migrations replaced by 13 safe, ordered files and the app code updated for dual-writes. What makes it different: the AI is not trusted — it is verified. A deterministic engine with real Postgres lock measurements judges; IBM Bob does the tedious, judgement-heavy surgery, in parallel, and must pass the same gate.
27 Sep 2026
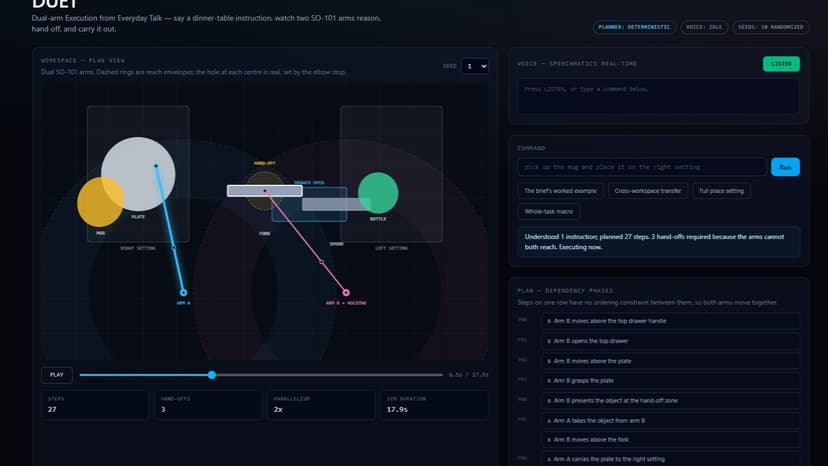
DUET — Dual-arm Execution from Everyday Talk
DUET turns a spoken sentence into coordinated two-arm manipulation. Say "Set the dinner table." and DUET transcribes it live with Speechmatics, parses it into structured intents, plans a dependency graph of arm actions, and executes it with both arms running concurrently: 27 steps, 3 hand-offs, 2x parallelism. Three things make that harder than it sounds. PRECONDITIONS. The cutlery starts inside a closed drawer, so it must be opened first, exactly once, however many later steps depend on it. Nothing instructs the planner to do this; it falls out of the dependency graph. HAND-OFFS THAT ARE FORCED, NOT SCRIPTED. Each place setting is verified at scene-generation time to sit inside exactly one arm's reach envelope, so moving an object across the table is physically impossible single-armed. When the holding arm cannot reach the destination and the other can, the planner inserts a give/take transfer. 28 hand-offs were required across 40 benchmark runs and none are special-cased. ROBUSTNESS. Placement, mass, friction, shape and lighting are randomized per seed. Grasps can genuinely fail, and failures propagate rather than being silently ignored. The planner is deterministic and no language model sits in the action path. A model may explain a plan; it never chooses one. The same sentence against the same seed yields a byte-identical plan, and the test suite enforces it. Measured: 39 of 40 seeded evaluation runs succeed (98%) in DUET's deterministic simulator, where success requires the command to plan with no errors, every step to execute, AND the world to end in the requested state. 53/53 automated tests pass. No physical robot is involved or claimed, and no OpenVINO or Intel Core Ultra execution is claimed. Runs entirely in the browser: no install, no sign-up, no microphone needed.
16 Sep 2026

ThesisCircuit
ThesisCircuit asks a different question from most trading agents: not “Can an AI generate a trade?” but “Can it produce a decision that remains safe, explainable, and idempotent under real operating conditions?” Three deterministic agents—Trend, Range, and Defensive—independently analyze current Alpaca market and options data. A Decision Council compares their typed theses, a Critic challenges stale evidence and hidden assumptions, and a deterministic risk governor has the final vote. Agent language can never override a rejection. NO TRADE, shadow ideas, and counterfactuals are preserved as first-class evidence without being shown as real broker activity. ThesisCircuit uses Alpaca’s official alpaca-py SDK and PAPER endpoint only. Supabase provides an RLS-protected audit trail, durable cycle locks, atomic order-intent claims, restart recovery, and bounded execution-session budgets. Railway hosts the FastAPI control plane, while the Vercel dashboard exposes account state, agent debate, risk decisions, the actual paper order lifecycle, and clear disclosures. The system proved its complete path with exactly one authorized opening order: one SPY Sep 4 $768 long call, submitted as a DAY limit at $1.88 and filled by Alpaca PAPER at $1.84. The planned maximum premium risk was $188. The proposal, 18-gate risk decision, fill, resulting position, and trace were persisted and rendered in production. No additional or closing order was placed. Production now rests fail-closed with execution and autonomous trading disabled. Bounded activation, shutdown, lock recovery, duplicate prevention, and eight-worker race behavior were verified synthetically with zero additional broker calls. SIMULATED PAPER TRADING — NO REAL FUNDS. Results are hypothetical and are not investment advice. Options carry significant risk, and all investments involve risk.
4 Sep 2026

LaunchMap AI
"LaunchMap AI is a client launch readiness workspace for small digital agencies, freelancers, implementation teams, startup studios, and client onboarding managers. These teams often begin a website, campaign, product, or integration launch with an incomplete brief. Important information is scattered across messages and documents, assets are missing, required integrations are unclear, ownership is undefined, and approval expectations are vague. The result is avoidable rework, late discoveries, missed dependencies, and stressful handoffs. LaunchMap AI turns that messy starting point into a structured, reviewable launch plan. A user starts a new assessment and enters company and project details, the public website URL, project type, written brief, expected launch date, and required channels or integrations. Judges can also load a safe fictional sample project immediately, so they can experience the complete workflow without creating an account or entering sensitive data. When the assessment runs, LaunchMap AI normalizes the submitted brief and produces an explainable launch-readiness analysis. The result includes an overall readiness score with category breakdowns, detected missing information, missing assets, dependencies, technical blockers, approval requirements, and launch risks. It also generates client follow-up questions, a prioritized action plan, owner assignments, and an editable launch checklist. Findings are connected to the information supplied in the brief so users can understand why an item was raised instead of receiving an unexplained score. The core product is more than a landing page or chatbot. It is a guided, multi-screen end-to-end workflow: start an assessment, enter project information, run the analysis, inspect structured findings, edit ownership and task status, review each section, approve the plan, save the result, and copy or print an approved report. Browser persistence keeps the working assessment available locally during the demo.
10 Aug 2026

CaptionForge AI`
CaptionForge AI is a Fireworks-powered video captioning prototype built for AMD Developer Hackathon Act II, Track 2. The app helps creators turn short videos into multiple ready-to-use caption styles without manually brainstorming different tones. A user uploads a short clip, optionally adds context or a transcript, extracts five representative preview frames, and generates four caption styles: formal, sarcastic, humorous-tech, and humorous-non-tech. The system uses Fireworks Vision through a secure Next.js API route to read sampled video frames and produce captions, a visual summary, and a safety note. If the selected vision model is unavailable, the app can fall back to Fireworks Text using the user-provided context, and if Fireworks is unavailable entirely, it keeps the demo running with mock captions. The goal is not to replace human judgment. CaptionForge AI is designed as a creative assistant where the user still reviews every caption before publishing. The interface clearly includes responsible AI notes, warns users not to misrepresent people or events, and avoids unsupported claims such as audio analysis or identity recognition unless the user provides that information. The project is built with Next.js, TypeScript, Tailwind CSS, Fireworks AI, and a Docker-ready production setup. It demonstrates a practical workflow for short-form video creators: upload, sample frames, generate captions, review, and copy.
13 Jul 2026


