
🤓 Latest Submissions
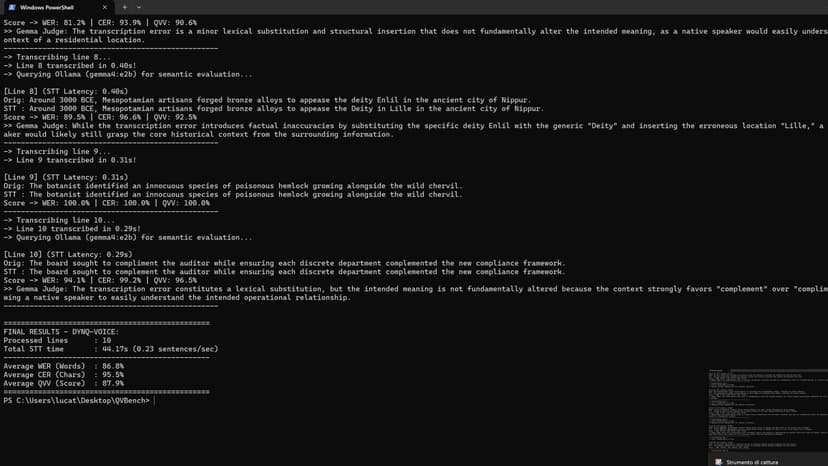
QVBench: tts stt semantic benchmark
DynQ-Voice is an edge-to-cloud benchmarking and inference suite engineered for enterprise telecommunications and sovereign AI deployments. Traditional speech benchmarks rely on Word Error Rate (WER), which severely penalizes models for trivial formatting discrepancies (numbers, currency symbols, and minor punctuation slips) while masking critical semantic degradation. DynQ-Voice introduces the proprietary QVV metric, providing a deterministic semantic-aware evaluation of speech pipelines. Tested under high-density acoustic streaming (1.8x velocity) with Kokoro v1.0 neural synthesis and CUDA/ROCm accelerated Whisper, the system demonstrates consistent sub-0.5s per-stream latency and 96% semantic accuracy, drastically cutting reliance on costly cloud telephony APIs.
18 Oct 2026
Quantum Voice Bench (QVBench)
Quantum Voice Bench (QVBench) is a high-performance benchmarking suite designed to evaluate the accuracy and resilience of Speech-to-Text (STT) models at scale. Currently, testing an STT model's accuracy across tens of thousands of audio samples takes days using traditional hardware, as files are processed sequentially. Furthermore, existing benchmarks rarely measure how transcription accuracy degrades when speech speed is artificially accelerated or when the system processes massive batches. QVBench solves this by fully parallelizing the evaluation process. By leveraging the massive VRAM bandwidth of cloud GPUs, our framework injects hundreds of simultaneous audio streams into the STT model in a single batch. The system automatically calculates the Word Error Rate (WER) against the ground-truth text. Crucially, QVBench allows developers to adjust the playback speed of the generated audio to test the true comprehension limits of the model. This enables AI engineers to benchmark large-scale datasets and get an "STT Report Card" in minutes instead of weeks, setting a new standard for voice model evaluation.
1 Dec 2026

