
mohamad ghahtarani@rezaghahtarani811
1
Events attended
1
Submissions made
Canada
1 year of experience
About me
I have been working in artificial intelligence and image processing field for more than 8 years. My main activities are the production of products and services based on artificial intelligence such as content moderation with deep learning. My main experiences are in text mining, image processing, and applying the GAN in industrial applications. I also have been the supervisor of artificial intelligence, technical team, and data team (collection, labeling, …) for 1 year. • Proficient in Python, • Proficient in Keras, • Proficient in Tensorflow, • Proficient in GAN, • Proficient in research.
I built with
VULTR🤝 Top Collaborators
Mohadeseh Moayedinia
🤓 Latest Submissions
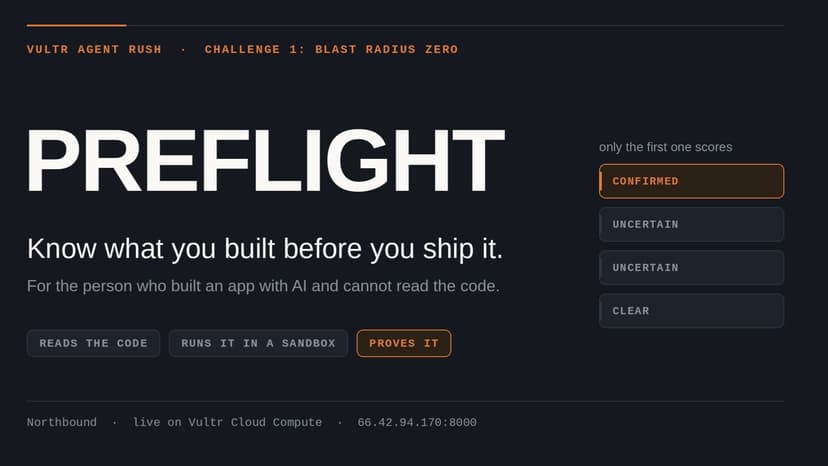
Preflight: know what you built before you ship it
Someone builds an app in Lovable or v0. It looks finished. They cannot read the code well enough to know if it is safe to show customers. 63% of people building on these platforms are not developers, and every tool that would tell them what is wrong was built for engineers. Preflight is written for them. Paste a repository URL. Three passes on Vultr Serverless Inference read the source and produce candidates, never conclusions. Reading code can show a problem is likely. It cannot show it happens. So nothing a model says is scored. The app is cloned into a sandbox on Vultr Cloud Compute and asked to misbehave. A fresh container per scan: no network, read-only root, unprivileged user, all capabilities dropped, 256 MB, half a CPU, a 64-process cap, a hard watchdog. The control plane on the Vultr VM holds every credential. The sandbox holds none. Three defects can be settled there with no judgement involved, and those are the only three we score: A primary button that does nothing. We click Pay and count network requests. Zero requests, no change, confirmed. A handler that crashes on incomplete input. We post a malformed payload and read the status and traceback. A page that never settles. We load it, watch CPU, and see if the watchdog kills it. Everything else is reported as uncertain, shown as worth a look, and deducts nothing. Preflight will not put a number on something it did not reproduce. Each confirmed finding comes back as a prompt written for the tool that built the app. Not a diff, not a patch for a developer to review. Paste it into Lovable, or let Preflight apply it and write the file. Rescan, and the score moves. We did not attack our own sandbox to show it holds. Scanning a real repository, a malicious install script reached for environment variables. The sandbox absorbed it, the kernel killed it, and it surfaced in the report as a finding.
8 Nov 2026
