
🤝 Top Collaborators

🤓 Latest Submissions
SYN: Guardian of the Production Manifold
Problem Modern software can pass unit tests and staging, yet fail structurally at production scale. An O(n²) path can look harmless on 100 rows and time out on 20,000. A shared resource can behave normally at low concurrency, then hit a capacity cliff as contention grows. Conventional tests validate correctness; load tests often discover these failures after code has merged. Solution SYN is a pre-merge gate that measures how a change behaves as scale and concurrency increase, then fits the laws behind those measurements. It uses two independent lenses: • Complexity: SYN sweeps input size across multiple scales, measures execution cost with repeated samples, and fits a growth exponent with a confidence interval. Superlinear growth is surfaced as WARN or REFUSED according to evidence-backed thresholds. • Stability: SYN measures latency across bounded concurrency levels and fits the Universal Scalability Law (USL). A nested statistical test determines whether the coherency term κ is supported by the data. When a capacity cliff exists, SYN derives its peak, separatrix, and headroom at expected load—without needing to drive the service into failure. The result is PASS, WARN, REFUSED, or UNKNOWN. UNKNOWN is first-class: when evidence is insufficient, SYN does not silently approve the change. Who uses it Backend engineers, developers, and engineering leads add SYN to CI and declare the functions or services to probe in syn.json. On a pull request, GitHub Actions runs the probes, posts the verdict and certificate, and blocks the merge when configured to refuse it. A live dashboard exposes the capacity curve, scaling law, statistical evidence, sensitivity analysis, and risk map. What makes it different SYN does not gate on a heuristic score or a single benchmark. It measures structural behavior and asks whether the observed law is statistically supported. It calibrates a no-op noise floor on the same runner, requires real κ to clear that floor, and refuses to trust a cliff that would require excessive extrapolation beyond the measured range. It also audits itself. During validation, GitHub’s runner exposed a false positive caused by scheduler-level timing noise that was not reproduced on the laptop. The noise-floor calibration and range guard were tightened, and the failure became a regression test. Proof SYN has been blind-validated on 9 anonymized targets, including trap negatives such as linear contention, an N+1 query, and an O(n log n) sort. Across 3 seeds on both a laptop and GitHub’s runner, it achieved 3 true positives, 0 false positives, 6 true negatives, and 0 false negatives per seed. Most importantly, SYN has refused a real GitHub pull request. A one-line change introduced a measurable coherency cost: κ = 1.07e-2, p = 1.7e-6, separatrix N = 14.5, with headroom of 1.23× at the tested operating load. The certificate was posted on the PR. Efficiency A gate run takes about 1–4 minutes on a standard runner and requires no always-on backend. Results are published as static data. SYN moves scaling and stability checks to the cheapest point in the software lifecycle: before merge.
27 Sep 2026
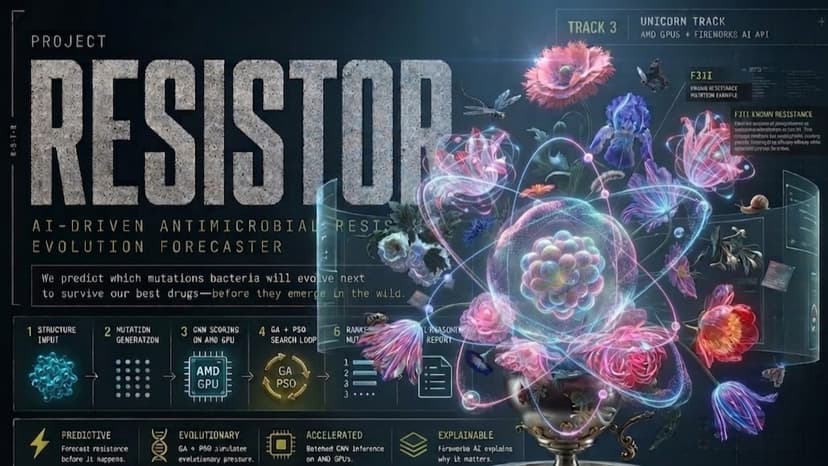
RESISTOR
Most AI drug discovery tools answer "which compound kills this bacteria today" — a crowded, reactive question. RESISTOR asks a different one: which mutations will this bacteria evolve next to survive our best drugs, before it happens in the wild. We built a genetic-algorithm and particle-swarm search loop — adapted from our prior project AETHER — to drive a trained graph neural network that scores binding-affinity and stability deltas for thousands of point mutations on a real, published protein-drug pair (S. aureus DHFR, PDB 2w9g). An attribution layer explains why each high-risk mutation matters structurally, and a live Fireworks AI integration turns that into a plain-language forecast report. Everything is tied together by an orchestration and verification pipeline that confirms every result is fresh and real before it's shown. We ran into real obstacles — AMD cloud access failures, a counterintuitive CPU-beating-GPU benchmark, twice-exposed API keys — and we disclosed all of it rather than hiding it, including a proven parity test and device-agnostic, ROCm-ready code. Our model independently rediscovers F98Y, a real clinical resistance mutation, computed fresh every run — proof this isn't scripted.
13 Jul 2026
Eidolon
Large language models are powerful generalists, but deploying them for specialized domains like legal, medical, or financial applications still requires expensive, time-consuming fine-tuning. Every new task means a new training run, new compute costs, and days of waiting. Eidolon solves this differently. Instead of fine-tuning the base model, Eidolon trains a hypernetwork to generate LoRA adapter weights on demand. Give it a task description and 50 domain examples, and it produces a specialized LoRA matrix set in under a second, injected directly into the frozen base model at inference time. No retraining. No queue. No cost per domain. The architecture centers on a 100M parameter hypernetwork that takes a task embedding from a frozen sentence encoder and outputs pairs of LoRA matrices (A and B) for each targeted attention layer of Llama 3.1 8B. The base model stays completely frozen throughout. Specialization happens entirely through the generated adapter weights. Built natively on AMD ROCm and optimized for the MI300X's HBM3 memory architecture, Eidolon exploits the hardware's massive bandwidth for meta-batch parallelism during hypernetwork training and holds multiple domain LoRAs simultaneously in memory during serving. The full stack runs on PyTorch 2.3+, HuggingFace PEFT, Flash Attention 2, Triton, and vLLM for production inference. The system was trained across 10 diverse domains simultaneously, using a task curriculum and gradient-aware techniques to prevent catastrophic interference between conflicting domain objectives. Generalization is evaluated on a held-out 11th domain the hypernetwork never saw during training. The result is a production-ready, few-shot domain adaptation system that makes LLM specialization as simple as an API call.
10 May 2026


