🤓 Latest Submissions
Homeward: discharge teach-back in 12 languages
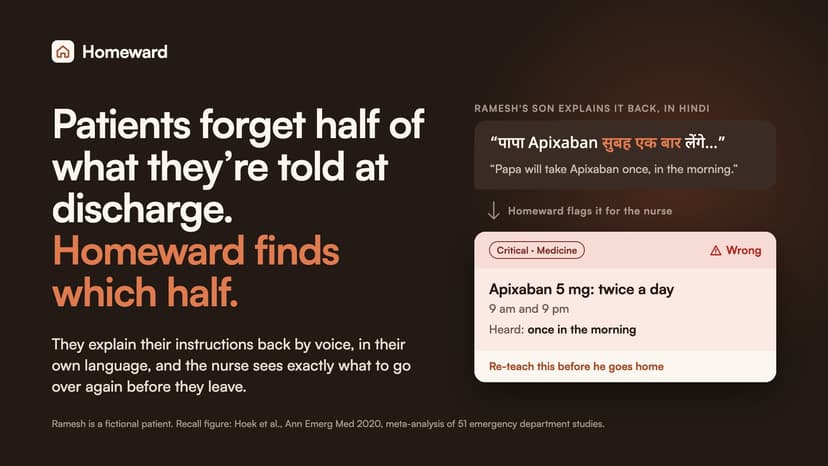
Of 33 patients observed through discharge, only 1 was asked to explain the plan back. When teach-back is done, the share leaving with a gap falls from 49% to 12% (Dutch ED trial). Nurses rarely have the time or the patient's language; Italy has 5.6 million foreign residents. The nurse pastes the note; Gemma 4 31B lists the facts the patient must understand and the nurse confirms them. Gemma writes them in one of 12 languages. The patient answers by voice, checks what was heard, and each fact is graded correct, partial, incorrect or missing. Misses are re-taught once. The board shows the patient's own words in English. Fact lock: DeepSeek V4 Flash translates every sentence back. Code checks each medicine, dose and date is there, then meaning is compared for negation, frequency and timing. Failures get two repairs, then go to the nurse. Planted-error test: 16 of 17 caught in 8 languages. On AMD: every model call in the demo runs on AMD GPUs via AMD Token Factory. Patient data shouldn't go to a cloud API, so we distilled Gemma 4 31B into Gemma 4 E4B with LoRA on one AMD Radeon PRO W7900D; one E4B both hears and grades on site, shown in the app's on-site replay. Results (150 answers in 12 languages, written by a different model family, never trained on): fine-tuned E4B 94.7% fact accuracy vs base 83.0%, Qwen3.8 Flash Next (180B) 91.2%, GLM-5.3 Flash (320B) 90.3%, MiMo-V2.6 Flash (309B) 88.9%, DeepSeek V4 Flash (284B) 80.4%; teacher Gemma 4 31B 97.1%. Critical misses graded understood: 1 of 108, the same as the 31B (base 5). Comparators ran zero-shot on our prompt. Speech, 15 real clips: E4B 20.2% word error vs Whisper large-v3-turbo 38.2%. Safety: no diagnosis or advice. "Understanding confirmed" is a code rule; the nurse decides. Synthetic patients only, nothing stored, not yet tested with real patients. Value: one full check costs $0.0015 to $0.0018 at Token Factory list prices, and the on-site version fits on one workstation GPU.
18 Oct 2026


