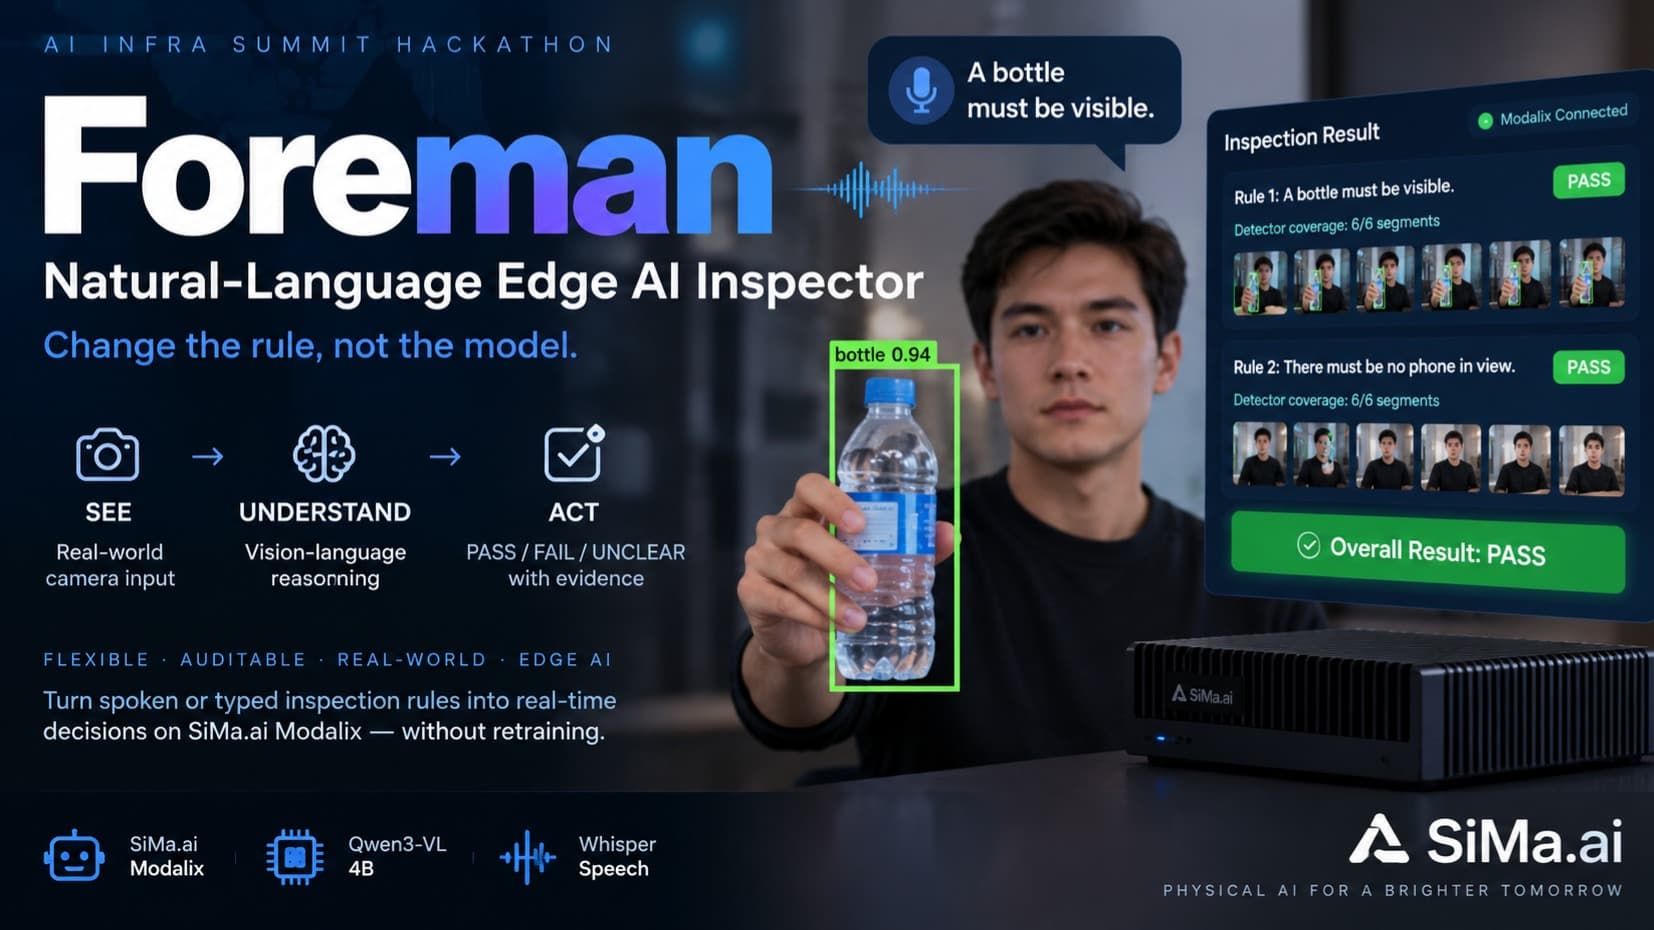
Foreman - Natural-Language Edge AI Inspector
Foreman is a natural-language Physical AI inspection system built on SiMa.ai Modalix. It allows an operator to change a real-world inspection standard simply by speaking or typing a rule, without retraining the underlying vision models. For example, an operator can define: “The person must be holding a bottle” and “The person must not be holding a phone.” Foreman observes the live camera feed, grounds objects across the full inspection window, selects temporal evidence, and uses Qwen3-VL 4B on Modalix to understand semantic relationships such as whether a person is actually holding an object. The system follows a SEE - UNDERSTAND - ACT architecture. SEE uses real-time object detection over the camera stream. UNDERSTAND combines speech recognition, temporal evidence, and vision-language reasoning. ACT applies deterministic policy logic to produce an auditable PASS, FAIL, or UNCLEAR result. Foreman supports up to two independent rules evaluated over the same physical capture, avoiding duplicated perception work. It also provides evidence frames, detector coverage, temporal coverage, per-rule explanations, inspection history, and CSV, JSON, and ZIP exports for traceability. The key idea is: change the rule, not the model. Instead of building a separate vision pipeline for every changing factory, safety, packaging, or compliance requirement, Foreman creates a reusable inspection layer that can adapt to new standards in seconds. The prototype runs on real SiMa.ai Modalix hardware with Qwen3-VL 4B, Whisper speech recognition, and an edge object detector, demonstrating an end-to-end Physical AI workflow from real-world sensing to an actionable decision.
Category tags:

For Innovators & Creators