EvidenceRAG — GPU-Powered Enterprise Document QA
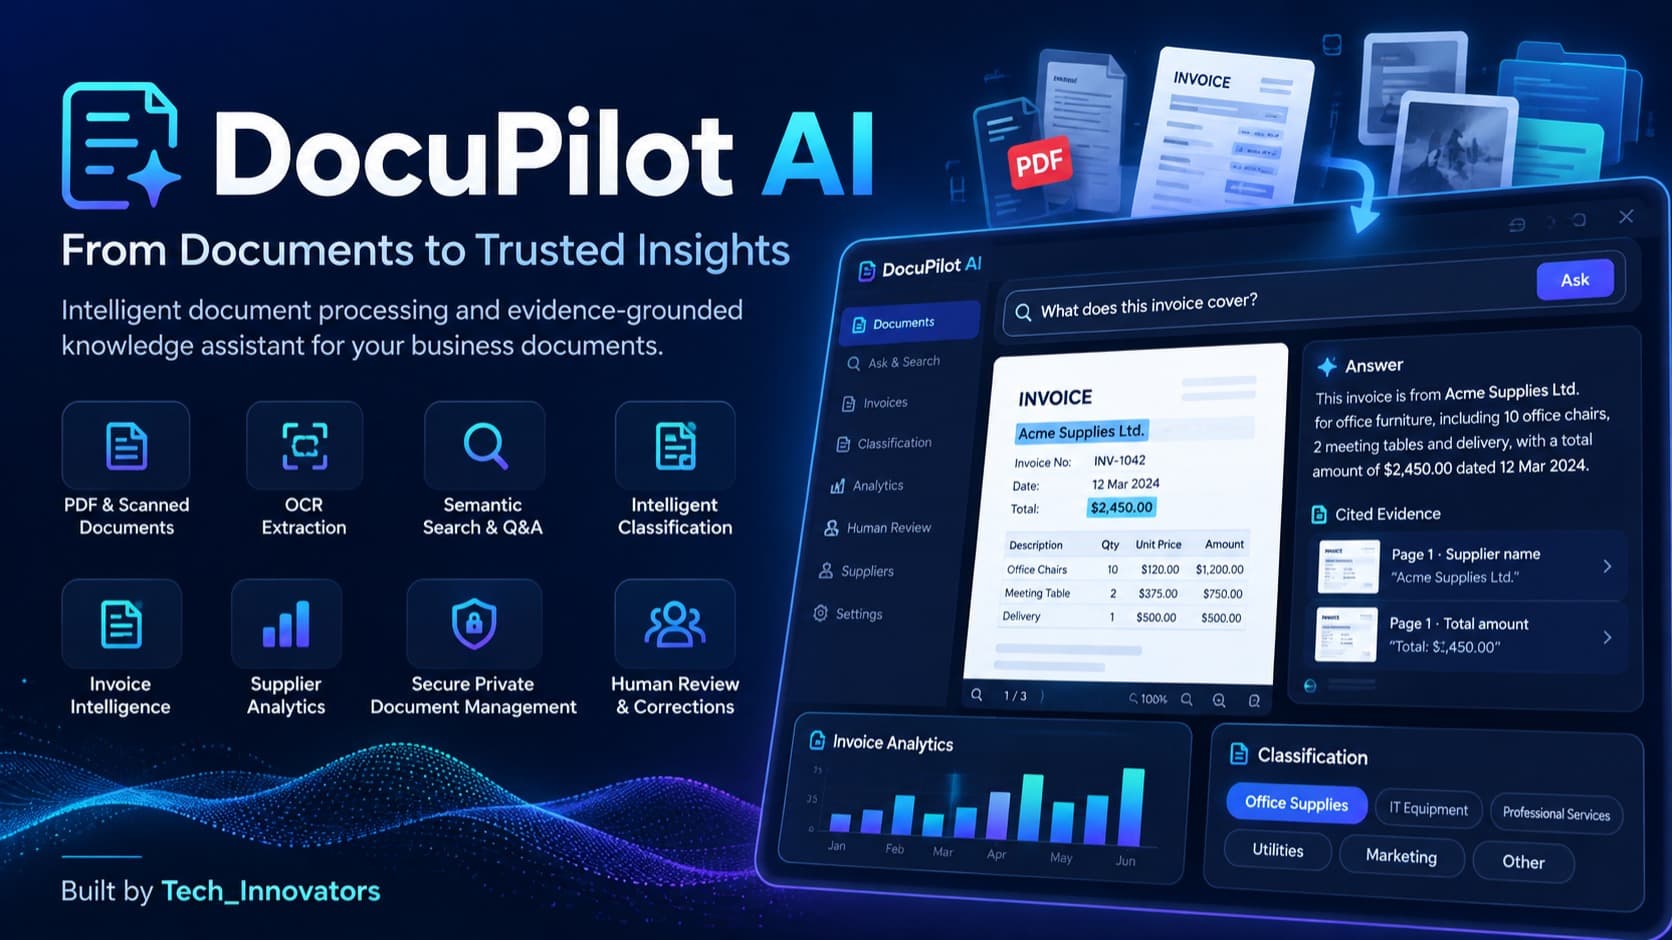
EvidenceRAG is a GPU-accelerated retrieval-augmented generation (RAG) system designed to answer questions from mixed enterprise document collections while identifying the exact files that support each answer.
The solution indexes PDFs, Word documents, Excel workbooks, CSV files, text files, production logs, Python source code, and images. It combines document parsing, OCR, pretrained semantic embeddings, and evidence-based retrieval to locate relevant information across different formats. The embedding model, sentence-transformers/all-MiniLM-L6-v2, converts document content and questions into vector representations for semantic similarity search.
A two-stage execution design separates indexing from question answering. During indexing, document content and embeddings are prepared for reuse. Each query then retrieves relevant evidence and produces a concise, value-only answer with corpus-relative source paths in a structured JSON response.
Citation precision is a core design requirement. The system aims to return only the files necessary to establish an answer, including multiple sources when a question requires connecting evidence across documents. When the corpus does not support an answer, it returns an empty answer and an empty citation list rather than guessing.
The container is designed for the AMD ROCm environment and the challenge's execution contract, including repeated query invocations, startup and query time limits, and resilience to empty directories, unreadable files, encrypted documents, and unsupported file types.
EvidenceRAG targets reliable enterprise knowledge retrieval, where correctness, traceability, and the ability to abstain are as important as finding an answer. Its objective is to make internal technical information easier to query while keeping every response auditable through precise document citations.