🤓 Latest Submissions
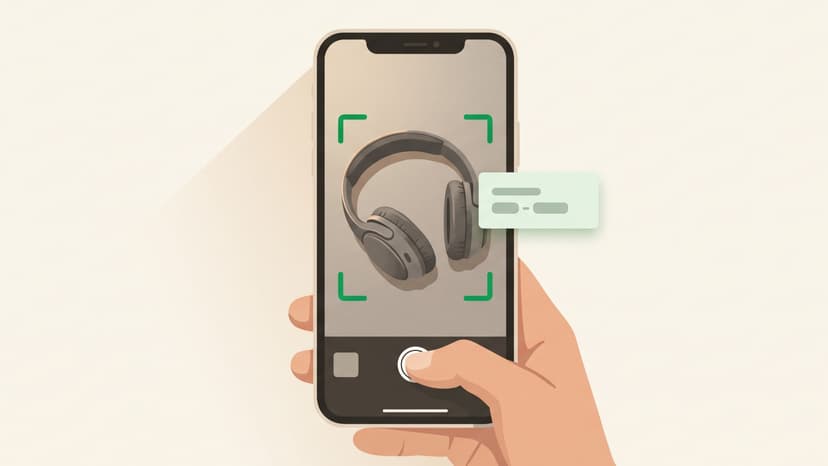
Kitna? Point your camera, know its worth
The problem. Nearly everyone in India has things they no longer use, and two questions stop the sale. What is it actually worth right now, and where do I sell it for the best return? Listings go stale, condition changes everything, and prices are scattered across Cashify, Quikr, Facebook Marketplace and WhatsApp groups with no way to compare them. Who it's for. People in India decluttering or upgrading, who know what they own but have no idea what it is worth, how to price it, or how to defend that price to a buyer. What Kitna? does. Point your camera at an item. On-device detection frames it in the live viewfinder and crops it, then a cloud vision model identifies the item and grades its condition, naming the specific wear it can see in your photo. Bright Data's SERP API pulls live listings from Indian marketplaces, and those real comps set both the resale range and its confidence band. You get a recommended sales channel, a ready-to-paste marketplace listing, and a Mol-bhaav haggling script with your asking price, your walk-away floor, and two Hindi-English counter-lines. Every number traces to evidence. The condition grade cites what the model actually saw. The price cites listings you can click. When no real comps come back, the app says so plainly and labels the figure an estimate. It never presents a price as live unless real listings back it. How native.builder was used. The Product Architect wrote the PRD from a plain-language spec. The Builder agent generated the Vite, React and TypeScript application, the design system, the camera capture hook and every screen, provisioned Supabase, and deployed the Edge Functions that keep all API keys server-side. The QA agent caught two dead-end bugs during live browser testing. External services. AI/ML API for vision with structured JSON output, Bright Data SERP API for live India comps, Speechmatics for voice, Supabase Edge Functions for secrets and runtime, and TensorFlow.js for on-device detection.
10 Aug 2026
Murmur: a society of minds that stress test ideas
Murmur is a message-response laboratory. Its demo population is a small world of intelligent minds with real professions, a doctor, a municipal officer, a cafe owner, a mechanic, a student and more, each with profession-true information habits, memory, and a research disposition. Every conversation is real inference: what you watch is propagation, not animation. Our Core Innovation: the entire society is resident on a single AMD Instinct MI300X. Gemma 4 26B A4B (MoE, about 4B active parameters) occupies 48.5 GB of the card's 192 GB, leaving 122 GB of KV cache and a measured 58.9x concurrency ceiling, served by vLLM 0.23 on ROCm 7.2.4. Every mind thinks concurrently on one card. Measured on hardware: message delivery to authority in 10/10 runs, median 4.5 ticks at 8.7 seconds per run; 65.6 percent mutation rate per retelling; throughput scaling 1367 to 4603 chars/sec as population grew 10 to 50 with near-flat per-tick latency; 100 percent GPU utilization at 178.9 GB VRAM under load; 1.99 dollars per hour on AMD Developer Cloud, roughly 4 cents per mind-hour. Minds research claims on the live web (Tavily) when a message touches their profession, and findings shape their stance. A probe lane (gpt-oss-120b on Fireworks at temperature zero) independently confirms every hop. A report endpoint writes each message's post-mortem. Emergence we never programmed, captured in logs: a mind refusing to act without a second witness, source-checking ("did you see it yourself or are you repeating her?"), and a victim correcting a misattribution of her own words. Roadmap: full idea trials, where researched minds form theses, deliberate pros and cons, and return a verdict on where an idea lands, at 50 plus resident minds per card. Markets: AI-native NPCs for game studios, synthetic-audience message pre-testing for brands, and a misinformation wind tunnel for institutions. MIT licensed; the README carries a one-command MI300X reproduction.
13 Jul 2026

Greenlight
The problem: before a financial ad can run, it has to clear several regulators at once. In India that means RBI, SEBI, and ASCI, three bodies with overlapping requirements. Today this happens in email threads, PDFs, and the heads of a few reviewers. It is slow, inconsistent, and when a regulator later asks who approved a claim and on what basis, there is rarely a clean answer. GreenLight turns that review into a coordinated agent workflow, and the workflow itself becomes the record. You drop an ad creative into a Band room. A Case Desk agent opens a case and picks the rulebooks. A Claims Analyst extracts every claim. When the creative touches investments, the Case Desk recruits a SEBI specialist into the room on the spot, only when needed. A Compliance Reviewer rules the advertising and lending standards in parallel. The Case Desk consolidates both into one verdict, and a human signs off before anything clears. Every step is the audit trail, captured as it happens. The system runs two AI stacks on purpose. The coordinating agents run on the Claude Agent SDK inside Band. The SEBI ruling, the highest-stakes reasoning in the pipeline, is produced by Anthropic Opus 4.8 served through the AI/ML API and invoked through a bridge. The AI/ML call runs at runtime on every case and its findings are tagged separately on the dashboard. It is real, not mocked. The dashboard renders each case as a downloadable clearance record: the creative, the agents and their frameworks, the coordination timeline with the live recruit marked, every finding with its rule ID, and the human sign-off. Live on Railway, backed by Postgres. The Indian rules are a demonstration, not a limit. The engine is regulator-agnostic: load FCA, SEC, or MAS rules and the same desk clears them. The room transcript becomes a system of record, so regulated industries get an audit trail for free, because the coordination is the trail.
19 Jun 2026


