

🤝 Top Collaborators


🤓 Latest Submissions

MarketPulse AI
### 🛍️ The Challenge Small and medium retail businesses (SMBs) operate on thin margins, losing over $1.1 Trillion annually to stockouts and excess inventory. Traditional enterprise supply chain suites are cost-prohibitive, complex, and require dedicated data teams. Independent retailers are forced to make procurement choices using static spreadsheets, leading to dead stock and lost revenue. ### 💡 The Solution: MarketPulse AI MarketPulse AI brings autonomous decision intelligence directly to SMB retailers. It functions as an autonomous merchandise director that analyzes SKU velocities, forecasts demand shifts, and generates optimal inventory rebalancing plans. MarketPulse AI coordinates a multi-agent decision pipeline: - **Demand Sensing Agent:** Models sales velocity, seasonality, and promotional trends. - **Pricing & Margin Optimizer:** Evaluates price elasticity to protect gross margins while clearing aging stock. - **Supply Chain Rebalancer:** Solves constrained optimization across lead times and holding costs. - **Autonomous Planner:** Synthesizes actionable purchase orders with clear rationale. ### ⚡ Powered by AMD Instinct™ MI300X & ROCm MarketPulse AI is engineered for AMD Instinct™ architecture. Real-time retail decisioning requires evaluating thousands of SKU combinations under tight budget constraints. Leveraging the high memory bandwidth and compute density of AMD Instinct™ MI300X with ROCm, MarketPulse AI executes multi-scenario simulations and linear optimizations in milliseconds with zero external API dependencies. ### 🌐 Built for Modern Commerce Featuring tactile budget controls ($10K–$100K presets), real-time executive KPI scorecards, and native 4-language localization (English, French, Spanish, Hindi), MarketPulse AI empowers retailers to make confident decisions in seconds.
18 Oct 2026
Memory Twin AI
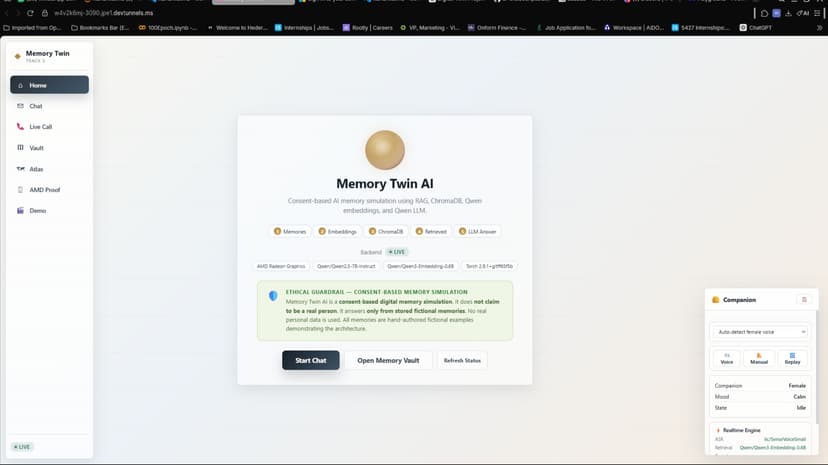
Memory Twin AI is a consent-based digital memory simulation designed for the AMD Developer Hackathon 2026. Instead of fine-tuning or training massive models from scratch, the system introduces an ultra-fast, explainable Retrieval-Augmented Generation (RAG) architecture running entirely on local AMD compute. By combining Qwen3-Embedding-0.6B and ChromaDB with Qwen2.5-7B-Instruct, the app achieves sub-second memory retrieval and response generation, pulling contextually relevant fictional memories out of a secure JSON vault based on cosine similarity. What makes Memory Twin AI truly unique is its intersection of radical engineering transparency and a warm, human-centric user interface. Every response inside the WhatsApp-inspired chat interface features a completely transparent "Explainable RAG Panel," mapping out the exact retrieval times, confidence scores, and models utilized. This pipeline feeds directly into a reactive 8-bit anime companion panel. Operating entirely via local browser TTS and lightweight Three.js bone rigs rather than slow, resource-heavy real-time video generation, the companion shifts expression, mood, and speech pacing dynamically based on the emotional category of the retrieved memory (such as humor, career, or childhood nostalgia). Built as a complete end-to-end prototype, the system includes a "Memory Atlas" timeline scrapbook, an automated multi-step Hackathon Demo Mode for video presentation, and a dedicated AMD Compute Proof screen that pulls live system metrics directly from the FastAPI backend to prove native ROCm/PyTorch acceleration.
13 Jul 2026


