🤓 Latest Submissions
TestGenAI: every test proves itself
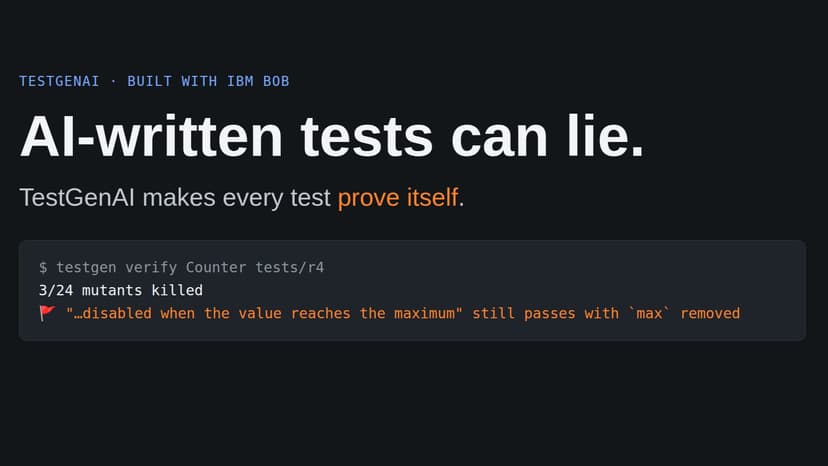
The problem. Teams now let AI write their tests, and the suite goes green. But a green test is not a useful test. Our first version generated 63 passing Playwright tests from user stories; against 28 planted bugs, they caught 3. The other 25 would have shipped green. Reviewing every generated test by hand defeats the point, and coverage can't tell you whether a test checks what its title claims. The solution. TestGenAI treats every test as untrusted until it proves itself, in three layers: (1) Generate. A deterministic generator (static JSX analysis plus 57 named rules, no LLM) turns a React component and its plain-English acceptance criteria into a Playwright spec. Each criterion becomes a real assertion labelled with the rule that grounds it in the code, or an honest test.fixme() when no rule can prove it. (2) Audit. IBM Bob works through our MCP server and a locked-down Test Engineer mode. It flags tests that assert the wrong thing, writes tests for the criteria we left pending, and fixes bugs the tests find. (3) Prove. testgen verify mutates the component automatically with 13 operators (callback dropped, condition inverted, guard removed, off by one…) and re-runs the suite. A test that never fails is unproven. A passing test whose title names something a surviving mutant deleted is a 🚩 suspect: the lie detector names the test that lies. Measured, not claimed. Every number is in a committed report, reproducible with one command. • Planted bugs: v1 caught 3/28; the current generator catches 27/28 on the same components. Across all 47 planted bugs in 17 components it catches 41, and 46 with Bob's tests added. • 224 acceptance criteria, 17 components: 201 asserted and passing, 23 honestly pending; regenerated byte-identical in CI. • Six blind rounds: Bob wrote a new component without seeing our code while our rules were frozen. The generator produced 17 flawed tests, and Bob's audit flagged all 17. On round 4's unedited suite, testgen verify flagged exactly the two green tests that lied ("disabled when the value reaches the maximum", tested on a counter disabled for another reason). • A generated boundary test found a real bug in a component Bob wrote blind: with step 3 and max 10, the counter went 9 → 12. Bob fixed it; the test went green. • testgen verify on all 17 suites: the generated tests kill 198 of 259 auto-derived mutants (76%). Bob's gap tests raise that to 234 (90%); of the 25 left, 21 are CSS-only or redundant-guard mutants. Why it matters. Code review, CI and releases all trust a green suite. TestGenAI gives that trust a basis: every test is proven against a real mutation or named as unproven or suspect, so reviewers read the few tests that need a human, not all of them. It also works on existing suites (testgen verify <Component> <testDir>), runs in CI, and plugs into IBM Bob as four MCP tools.
27 Sep 2026

