🤝 Top Collaborators
🤓 Latest Submissions
Brainstormer - A autoimproving personized agent
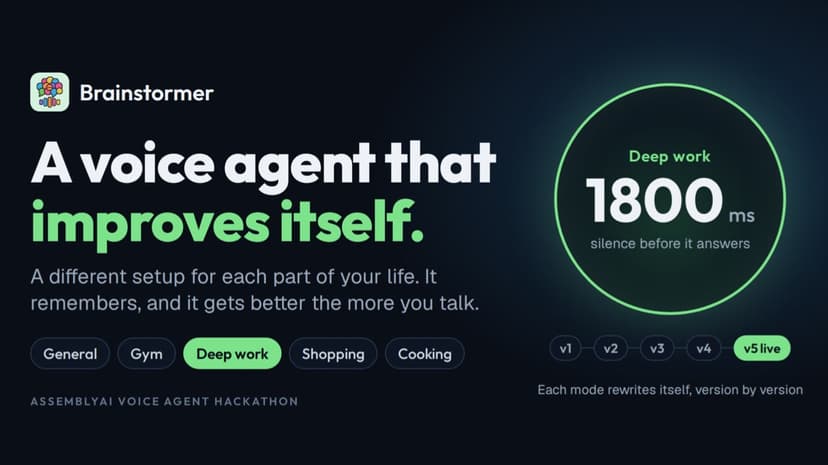
Brainstormer is a voice agent that knows which part of your life you are in, remembers it, and gets better by itself. Try the demo. Username: anything. Password: Vishpatya@123. Limited to 15 users. Contact: [email protected] Why we built it In a text chat, you open a new chat for each topic. On a voice call there is only one thread. You jump from topic to topic, and the agent has to keep up. Most voice agents use one prompt for everything. We saw three problems: - One style does not fit every topic. At the gym you want a short answer. For a technical question you want the agent to wait and explain. - It forgets. The last call is gone when you hang up. - Mistakes stay. When a reply goes wrong, nobody fixes the prompt. What Brainstormer does It has a different setup for each part of your life. We call each setup a mode: Gym, Deep work, Shopping. Each mode has its own prompt, its own waiting time, its own tools and its own memory. - You talk about a new subject, and the mode changes by itself. The call does not restart. - You talk about something new, and a new mode is created during the call. - After each call, every reply is checked. If a mode keeps making the same mistake, a better version of it is written. - Every version is saved. You can see what changed and why, and go back to an older one. - A mode you do not use for 30 days goes to sleep. It wakes up when you talk about it again. How it is built AssemblyAI Voice Agent API runs the call. The Jev decision model picks the mode. A model on Fireworks AI writes the better versions. Exa does the web search.
30 Sep 2026

Scam Call Shield
Voice cloning is now so realistic that just three seconds of audio can imitate someone’s voice, and AI voice scams increased by 1,210% in 2025. Scam Call Shield protects users during live calls in two ways. Whisper transcribes speech locally, while an open LLM running on Fireworks analyzes the conversation for scam patterns and warns the user. At the same time, a wav2vec2 model, fine-tuned and evaluated on AMD GPUs with ROCm, checks every three seconds for AI-generated speech. This catches cloned voices that sound normal. Our model achieved 98.8% accuracy on real-world deepfakes and 87.4% on unseen speakers.
13 Jul 2026


