Syuja Dewa Kusuma@whard220599
5
Events attended
4
Submissions made
Indonesia
1 year of experience
About me
I'm Dewa, an AI Engineer who builds production-ready systems fast. I recently shipped SignalScout — a live GTM intelligence platform with Claude Haiku, Bright Data APIs, MCP JSONRPC endpoint, and 214 passing backend tests, deployed on Google Cloud Run and Vercel during a hackathon. My stack: Python, FastAPI, Claude/Gemini, pgvector, Google Cloud Run. I focus on systems that are auditable, tested, and actually deployed — not just demos. I also built a production Telegram AI superapp for a real business client, reducing their manual work from 90 hours to 15 minutes per month. I'm here to build something that ships, not just something that looks good in a slide deck.
🤝 Top Collaborators

🤓 Latest Submissions
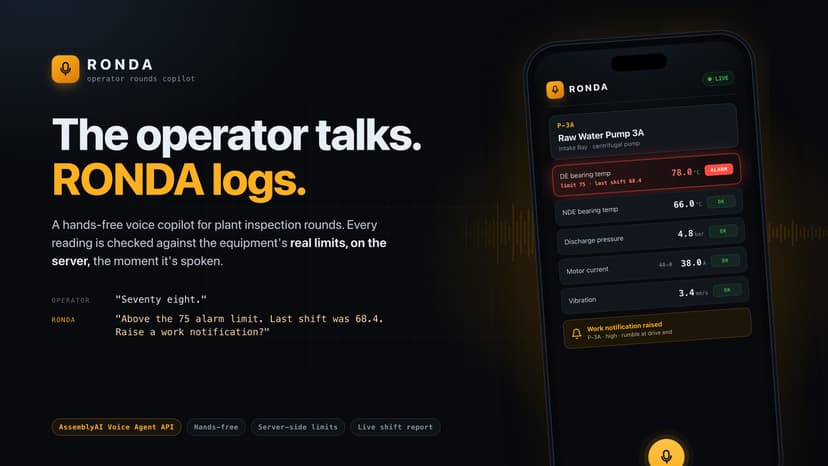
RONDA Voice Copilot for Operator Rounds
Every plant with rotating equipment runs operator rounds: someone walks the site each shift, reads gauges on pumps, blowers and motors, and writes the numbers on a clipboard. They wear gloves, it is loud, and typing is not an option. The data reaches a system hours later, so a reading already past its alarm limit gets noticed after the bearing has failed. RONDA replaces the clipboard with a conversation. The operator names an asset, the agent loads its check points, and the operator speaks the numbers. Each reading is logged, checked against that equipment's limits, and read back aloud. On a breach the agent quotes the limit, recalls last shift's value, and offers to raise a work notification, which is sent to Telegram. A supervisor can follow the round live, and the shift report writes itself at the end. Key design rule: the model never decides whether a reading is safe. The server computes ok/warn/alarm and the agent only reads the verdict out, so the SQLite audit trail stays authoritative. Corrections supersede rather than overwrite, and ambiguous check names are refused instead of guessed. Built on the AssemblyAI Voice Agent API: one WebSocket for speech in and out, turn detection tuned for dictation, keyterms for asset tags, and four HTTP tools AssemblyAI calls directly. The report is generated through the AssemblyAI LLM Gateway. Plain Node.js, zero npm dependencies, 40 tests.
30 Sep 2026

Classifi
What if anyone could build a custom AI classifier in minutes, not weeks? Classifi transforms as few as five labeled examples per category into a working text or image classifier, with no model training, complex pipelines, or machine-learning expertise required. Users simply define their categories, add examples, and classify new content instantly. Every prediction includes a confidence score and a plain-English explanation, turning AI from a black box into a tool people can understand and trust. Under the hood, Classifi converts user examples into structured few-shot prompts for multimodal Gemma 3, served through Fireworks AI on AMD Instinct GPU infrastructure. This enables fast, scalable inference without requiring users to manage the underlying infrastructure. Once created, each classifier can also be exposed through a reusable REST API endpoint and integrated into real applications and workflows. From teachers assessing assignments and manufacturers detecting defects to researchers organizing data and NGOs sorting multilingual field reports, Classifi puts practical, explainable AI in the hands of the people who understand the problem best. Open-source, self-hostable, and training-free, Classifi is not merely a prototype, it is a faster, more accessible way to transform domain knowledge into specialized AI.
13 Jul 2026

NexusCore
NexusCore is the governance brain and emergency brake that sits above AI agent teams. Built for the Band of Agents Hackathon, it addresses a growing enterprise risk: AI agents are no longer only suggesting code. They can generate patches, call tools, modify databases, deploy services, and trigger live actions faster than humans can review them. NexusCore adds governance before execution. When an agent proposes or attempts an action, the system classifies it into LOW, MEDIUM, or CRITICAL risk. LOW actions are allowed and logged. MEDIUM actions are held for review. CRITICAL actions are stopped and require explicit human confirmation before they can proceed. The system uses nine specialized agents collaborating through Band: Engineer/Builder, Proposer, Risk, Compliance, Security, Test, Infrastructure, Rollback/Audit, and Master. The Proposer Agent turns risky work into a formal proposal. Reviewer agents assess blast radius, reversibility, security, policy, test readiness, infrastructure impact, rollback plans, backups, and audit evidence. The Master Agent reads all findings and issues the final ALLOW or BLOCK decision. Band is central to the workflow, not just a notification layer. It acts as the shared collaboration room where agents exchange context, post reviews, coordinate decisions, and create a visible reasoning trail. The NexusCore dashboard mirrors this process with live workflow status, agent architecture, runtime interception, pending approvals, and an audit ledger. NexusCore demonstrates a practical enterprise use case for collaborative agents: making autonomous AI workflows safer, traceable, and human-governed before they touch production systems.
19 Jun 2026
SignalScout AI: Evidence-First Why-Now Engine
SignalScout AI is an evidence-first why-now engine for GTM and sales teams. Sales reps often spend hours researching accounts, but still reach out too late, with generic messaging and black-box intent scores. SignalScout answers one practical question: why should we contact this company right now? The system uses Bright Data as the live public-web data layer. SERP API collects fresh news, funding, product, and competitor signals. Web Unlocker extracts full text from hard-to-access pages. Web Scraper API provides pre-warmed hiring snapshots for directional hiring evidence. The backend then converts these signals into typed evidence rows with source URLs, source tiers, confidence, mode labels, and a reproducibility hash. Unlike typical AI sales tools, SignalScout does not let the LLM generate numeric scores. Scores are computed deterministically in Python from explicit signal weights, impact, confidence boost, and mode multiplier. Claude Haiku is used only for evidence-grounded synthesis: executive summary, why-now reason, sales angles, cold email, LinkedIn message, and discovery questions. The product is deployed as a live cockpit on Vercel with a FastAPI backend on Google Cloud Run. Each run shows the agent pipeline, evidence ledger, scoring audit trail, Bright Data infrastructure usage, and action pack. The result is a sales-ready GTM brief that is live, deterministic, and traceable.
31 May 2026


