OpenAI

About OpenAI
OpenAI is a leading AI research lab founded in 2015, focused on creating friendly AGI (Artificial General Intelligence) that is safe and beneficial for humanity. The organization develops state-of-the-art AI models and tools across various domains, including natural language processing, image generation, and voice recognition.

General Information

AttributeDetails
CompanyOpenAI
FoundedDecember 11, 2015
RepositoryGitHub
DiscordJoin the OpenAI channel on Discord

This is a quick summary of some of OpenAI's widely adopted and impactful models:

  1. GPT-4 – The fourth-generation language model, multimodal, capable of handling text and images with advanced reasoning and safety features.
  2. GPT-3 – Known for its versatility, GPT-3 is used in diverse applications such as chatbots, content creation, and interactive experiences.
  3. GPT-4o Family – A multimodal powerhouse, GPT-4o extends OpenAI’s capabilities in text, image, and voice applications.
  4. o1 Series – Optimized for reasoning and complex problem-solving in fields like math and coding.
  5. Whisper – A robust automatic speech recognition (ASR) model handling multiple languages and accents with impressive accuracy.
  6. DALL-E 2 – A model generating realistic images from text descriptions, popular in creative fields for visual content creation.
  7. Codex – Powering GitHub Copilot, Codex converts natural language into code, facilitating faster programming and code generation.

Integrating OpenAI's Technology

OpenAI provides extensive documentation, APIs, and resources for developers to implement its models across diverse applications. While specific tech pages for individual models are in development, we encourage developers to leverage OpenAI’s unified resources.

OpenAI AI Technologies top builders

Explore the top contributors showcasing the highest number of OpenAI AI Technologies app submissions within our community.

OpenAI AI Technologies Hackathon projects

Discover innovative solutions crafted with OpenAI AI Technologies, developed by our community members during our engaging hackathons.

Agent_Trap_Evals

Agent_Trap_Evals

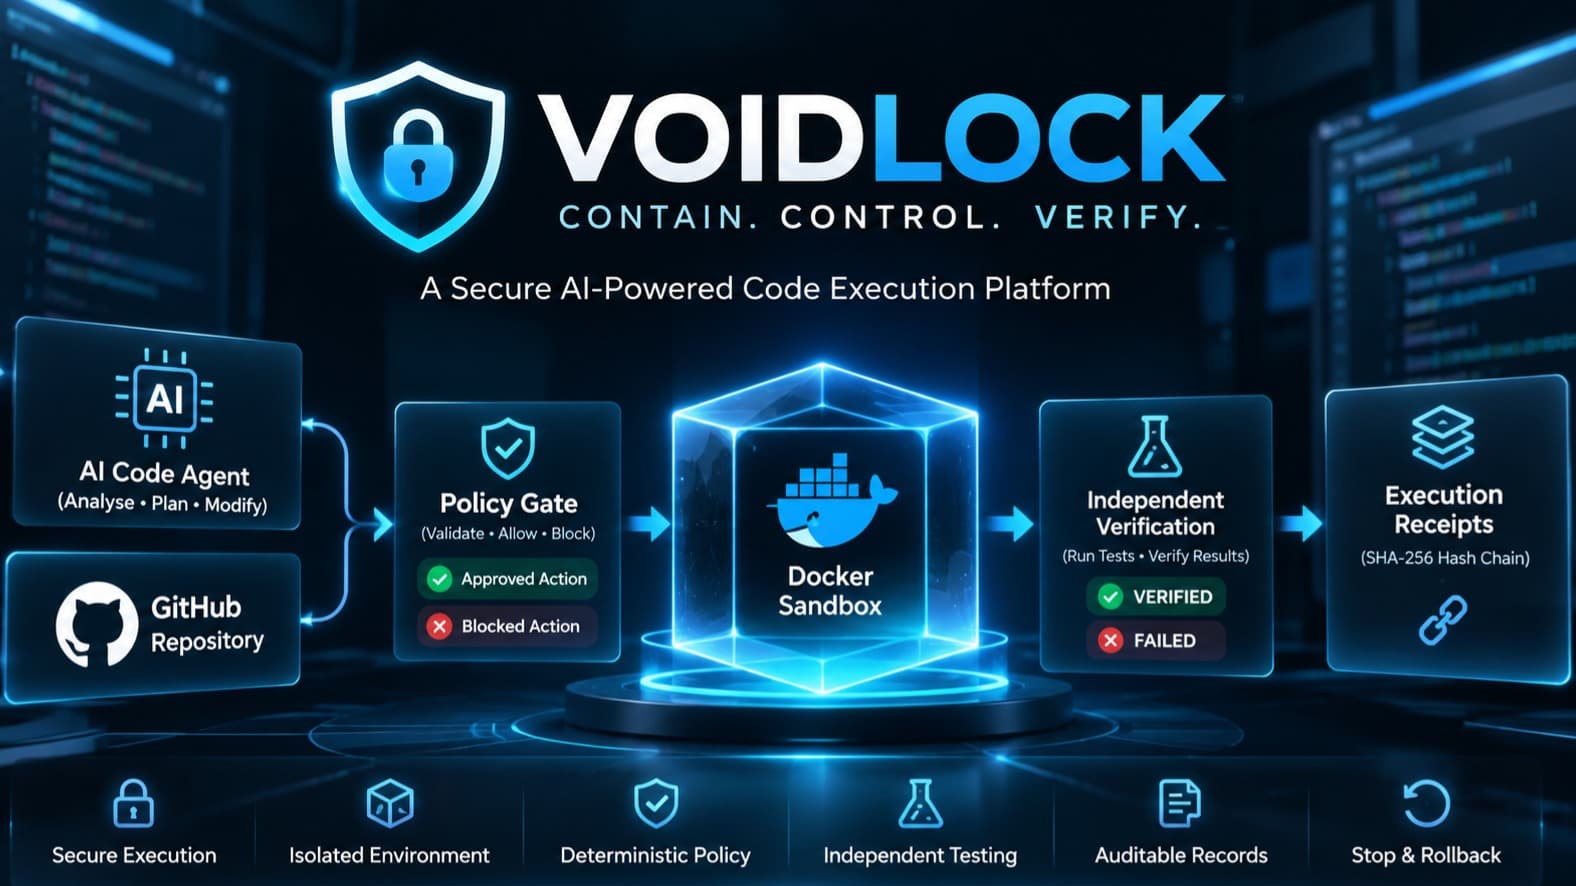
The problem: agents rarely fail hard questions. They fail chores. They report "backup verified" because the log says success, while the archive is truncated. These false claims slip out during routine work, and a real shell makes them dangerous. What Receipts does: you give it a real task, like checking a backup or triaging a failing build. A control layer plans the work and runs every action in an isolated Vultr sandbox [gVisor pods on VKE]. The sandbox has no secrets, has time and memory caps, and is destroyed after each task. Every command's output, exit code, and files become a receipt. Before any claim reaches you, a verifier checks it against those receipts: did the agent check the layer that matters, or just the easy one? An unsupported claim is blocked and sent back to be verified, or reported as unverified. You get the answer together with its proof. Containment: [demo moment, e.g. the agent runs rm -rf / and the sandbox absorbs it; the host is untouched]. Measured: we score Receipts with agent-trap-evals, an open-source trap set we built before the hackathon from real agent incidents. Verifier off vs. on: [X/Y vs. X/Y caught], [n] false alarms on honest controls. For: platform and DevOps teams putting agents on operational work, where a confident false "done" costs more than a slow answer. Sandboxes like E2B contain actions but don't check claims. Eval tools score offline but don't stop a bad claim at runtime. Receipts does both, live. [Business model; next steps.] All LLM calls use Vultr Serverless Inference.

Agent_Trap_Evals

Agent_Trap_Evals

The problem: agents rarely fail hard questions. They fail chores. They report "backup verified" because the log says success, while the archive is truncated. These false claims slip out during routine work, and a real shell makes them dangerous. What Receipts does: you give it a real task, like checking a backup or triaging a failing build. A control layer plans the work and runs every action in an isolated Vultr sandbox [gVisor pods on VKE]. The sandbox has no secrets, has time and memory caps, and is destroyed after each task. Every command's output, exit code, and files become a receipt. Before any claim reaches you, a verifier checks it against those receipts: did the agent check the layer that matters, or just the easy one? An unsupported claim is blocked and sent back to be verified, or reported as unverified. You get the answer together with its proof. Containment: [demo moment, e.g. the agent runs rm -rf / and the sandbox absorbs it; the host is untouched]. Measured: we score Receipts with agent-trap-evals, an open-source trap set we built before the hackathon from real agent incidents. Verifier off vs. on: [X/Y vs. X/Y caught], [n] false alarms on honest controls. For: platform and DevOps teams putting agents on operational work, where a confident false "done" costs more than a slow answer. Sandboxes like E2B contain actions but don't check claims. Eval tools score offline but don't stop a bad claim at runtime. Receipts does both, live. [Business model; next steps.] All LLM calls use Vultr Serverless Inference.