

🤝 Top Collaborators


🤓 Latest Submissions
GREPO — Find Your Way Through the Code
A repository is easy to clone and hard to understand. Before making a useful change, a developer must discover where behavior lives, how modules connect, what can be reused, and what might break. That knowledge is scattered across file trees, searches, documentation, and teammates' memories. GREPO brings it into one workspace: a connected path from repository structure to source evidence to a reviewable next step. Import a public GitHub repository or ZIP to create a read-only snapshot. Start with the overview, search the file tree, explore an interactive repository map, and open the corresponding source without losing your place. Shared selection and source ranges keep the map, files, and findings connected. The dependency explorer traces supported static imports and function calls, attaches source evidence, and explains unresolved relationships. Reusable functions, duplicate patterns, and potentially unused code become concrete starting points for investigation. File and folder summaries surface inventory and syntax facts. Coverage information helps developers judge what the analysis can establish. The recorded workflow also demonstrates optional AI assistance. Ask a repository question, inspect the cited excerpts, and follow them back to source. Describe an improvement to generate a change proposal with affected files, suggested checks, and open questions. Create an onboarding guide, repository overview, or developer reference, then edit and export the Markdown. These outputs remain reviewable drafts; the imported code stays untouched. GREPO is designed for developers joining a codebase, maintainers investigating unfamiliar modules, and contributors preparing a change. Its value comes from keeping exploration, explanation, and planning close to the evidence. Instead of rebuilding context in separate tools, users can carry what they discover directly into their next question or decision. Underneath the interface, snapshot-scoped identifiers, source hashes, bounded reads, and explicit unresolved states provide a traceable foundation. Core exploration runs locally without executing imported code. Optional Groq-powered AI works through the backend with selected source excerpts. React and TypeScript power the interface; Python, FastAPI, Tree-sitter, and Archify support analysis and visualization. IBM Bob was a central development tool for the team's implementation and corrective engineering. GREPO helps developers find their bearings, inspect the evidence, and approach the next change with a clearer understanding of the code.
27 Sep 2026
O(1) Agent
O(1) is a hybrid AI orchestration platform that intelligently routes every request to the most efficient execution path, balancing accuracy, latency, and operational cost. Instead of treating every prompt equally, the system analyzes task complexity and dynamically selects the optimal execution strategy. The routing pipeline begins with T0, a deterministic Python engine capable of solving structured, factual, mathematical, classification, and rule-based tasks instantly without invoking an LLM, resulting in zero LLM inference cost. Requests requiring language understanding are automatically escalated to T1, where multiple Gemma 4 models are served locally on AMD GPUs using ROCm and vLLM. This provides responses that are fast and of same accuracy while spending less on premium models. When local inference is insufficient or a request exceeds predefined routing criteria, does the router escalate to T2, a cloud-hosted LLM, where prompts are optimized to minimize token consumption while preserving response quality. Beyond routing, the platform includes automatic task classification, adaptive model selection, token-efficiency profiling, latency benchmarking, structured request logging, performance analytics, response caching, and real-time streaming using Server-Sent Events (SSE). Built-in benchmarking and monitoring provide detailed insights into throughput, latency, GPU utilization, cache performance, and routing decisions, making the system suitable for both production deployments and research workflows.
13 Jul 2026
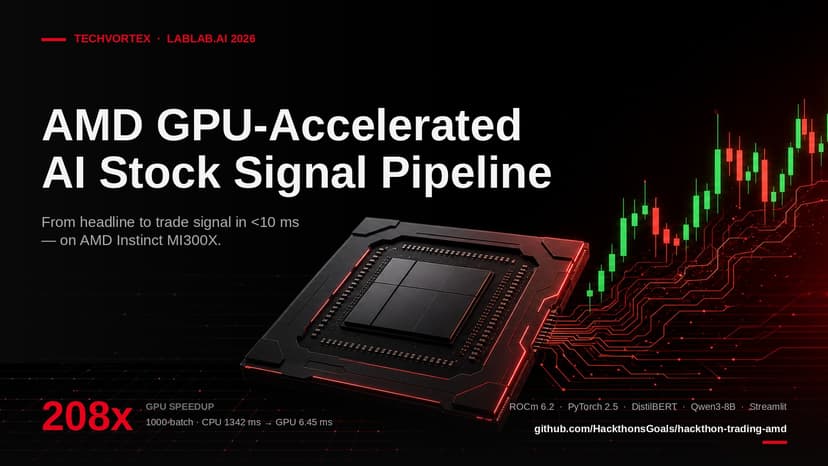
Sentiment Analysis of a Stock Data on News
We built an end-to-end AI stock signal pipeline that turns live market data and news headlines into explainable trade signals — fully accelerated on AMD Instinct MI300X via ROCm + PyTorch. The system runs three cooperating agents in an agentic workflow: 1. Signal Agent — pulls live OHLCV and headlines via yfinance, computes rolling-volatility regimes (LOW/MED/HIGH), and runs batched market inference on GPU. 2. Sentiment Agent — a fine-tuned DistilBERT classifier from Hugging Face Hub (POS/NEU/NEG with signed scores) running batched ROCm inference for thousands of headlines per second. 3. Reasoning Agent — Qwen3-8B generates a natural-language explanation for each BUY / SELL / HOLD decision, with entry, stop-loss, and target levels. A simulated execution engine then runs an OPEN-to-CLOSED trade lifecycle with slippage and P&L, surfacing win-rate, average return, and a cumulative P&L curve. The Streamlit dashboard exposes a live GPU diagnostics banner, KPI tiles, signal table, sector heatmap, sentiment analytics, and CPU-vs-GPU throughput charts. Verified on AMD Developer Cloud (ROCm 6.2 + PyTorch 2.5.1+rocm6.2): 17.0x speedup on 100-batch market pipeline, 208.0x on 1000-batch market pipeline, 14.49x on sentiment batch — all from the exact same code path that runs on CPU. AMD-first, IP-safe, judge-friendly, and built to scale to multi-GPU MI300X clusters.
10 May 2026
Autonomous Treasury Management Dashboard
AutoPilot is a full-stack platform designed to monitor, manage, and audit autonomous treasury rebalancing agents. The dashboard interface allows users to oversee critical system metrics such as active agents, queue depth, execution success rates, and error rates. By presenting each metric in an intuitive, analytics-driven UI, AutoPilot improves operational awareness and decision-making for teams managing automated treasury workflows. The platform includes dedicated sections for tasks, executions, approvals, audit logs, agent health checks, and system settings. Each module is structured to streamline oversight of automated processes while providing transparency, accountability, and performance insights. The system also includes real-time status indicators, activity trends, and agent-level health reports to ensure reliability at scale. The goal of AutoPilot is to provide a unified operational interface for teams working with autonomous financial or treasury automation agents, reducing human error while enhancing control, efficiency, and visibility across the entire automation pipeline.
7 Dec 2025
Llama Proxy
We propose using the LLaMA 3.1:1B model as a local proxy server to manage caches with JSON responses. Here's how the llama model can help us do just that: Query analysis and optimization Smart data management in the cache Optimization of communication with API Create intelligent cache management policies. Enrich responses and adding a layer of security and privacy to the application. Understand user behavior and tailor data to their needs. We can also approach the problem using the cloud model, when we do not have enough RAM to be able to run llama 3.1:1B. We can then send queries from time to time to the server, which would decide on the cache hierarchy, which would be the most important, and which items would already have a deletion time.
20 Oct 2024


