

🤝 Top Collaborators

🤓 Latest Submissions
CLARIO
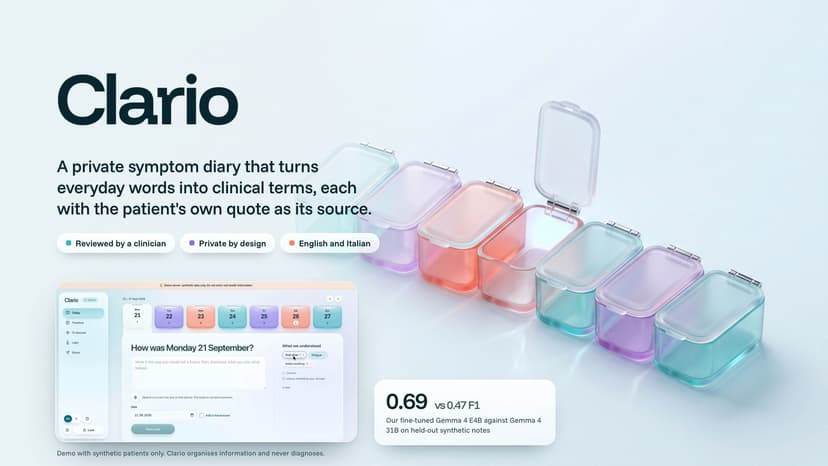
300 million people live with a rare disease, most starting in childhood. Diagnosis often takes over five years: appointments, inconclusive tests, the same story retold. The clues may already exist: a forgotten symptom, a lab value buried in a PDF, a pattern no single visit revealed. What if we could connect those dots sooner? CLARIO connects patients with unexplained symptoms and the doctors looking for answers. Patients keep a diary in their own words, by voice or text, and upload lab reports. CLARIO links clues across months and asks the one question that would help most. Clinicians get a dashboard with the history, symptom and lab trends, rare conditions worth considering, and an evidence-backed brief. Every AI finding can be traced, corrected or rejected, and the brief is a draft until a doctor signs it. Privacy is engineered in: AES-256-GCM vault, Argon2id keys, pseudonymisation before any remote call, tamper-evident AI logs, X25519-sealed sharing, on-device transcription. Bigger isn't always better. Our LoRA-tuned Gemma 4 E4B reaches F1 0.70 on 300 disease-held-out cases (0.35 before tuning), with 100% valid JSON and 99.8% quote grounding. On 100 of those cases, scored the same way, it beats Gemma 4 31B: 0.69 vs 0.47. On AMD: Gemma 4 31B on AMD Token Factory wrote our 2,992-diary training set, reads lab PDFs with MinerU (48/48 rows) and drafts the brief. Our fine-tuned model runs offline on an AMD Ryzen CPU (F1 0.64), so the diary can stay on the patient's computer. Also tested on real patient text (PsyTAR). Every number links to a file in the repo. We don't replace doctors. We help the patient's whole story reach them, because five years is too long to wait to be heard.
18 Oct 2026
The Dark Factory: Cheapest Hands First
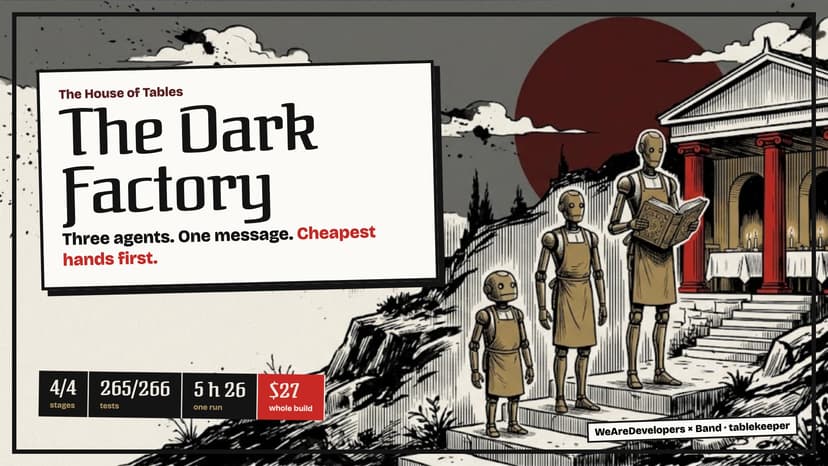
The Dark Factory is a three-seat agent team in Band Desktop that turns a written spec into a staged, containerised service from one human message. We pointed it at tablekeeper, a restaurant booking system that must never double-book a table under concurrency, retries and time zones, and left the room. Two ideas drive it. First, the shipped checks are a sample; the spec is the test. Only 11% of stage 3 tests ship, so our architect (Opus 5.5) turns every spec sentence into a numbered requirement and writes a black-box test suite before any code exists: wrong JSON types, stray whitespace, exact fields, retries, bursts of 50 requests, daylight-saving edges, data upgrades, every screen at 375 px. Second, the cheapest model that passes wins. Each task climbs a ladder: Haiku 4.5 gets two attempts, Sonnet 5.5 two more, and the architect finishes only if both fail. The architect re-runs every claimed success itself, so a cheap model can be wrong, just never wrong and accepted. In the submitted run Haiku finished 4 of 9 tasks, all first try, Sonnet 5, Opus 0. The room shows real teamwork: the architect caught a Haiku UI at 370/390 and sent a product review of its screenshots; Sonnet rewrote it to 391/391. Later the fixer proved two of the architect's own tests contradicted the spec, and the architect agreed and fixed them. Results: all 4 stages pass the official checks in isolated Docker, 265/266 of our spec-derived tests, 5 h 26 min, $27.46, about half the cost of our earlier five-seat factory at the same quality. Mandates never name a product or endpoint. FACTORY.md, mandates, room.json and 16 measured runs are in the repo.
6 Oct 2026
Iris: assistant for ones who can't see the screen
Iris is a voice that uses your computer for you. For 338 million people who are blind or have serious vision loss, a screen full of buttons is a wall. Screen readers help only where developers labelled every button; otherwise you hear "button, button, button". About 95% of the top million websites fail basic accessibility checks, so many people depend on a sighted helper. Iris removes that need. Say what you want in plain words ("did my grandson write?", "order more vitamin D") and Iris does it in the app on your Windows PC, tells you what happened, and asks out loud before anything that sends, pays or deletes. It needs nothing from the app's developer: an API when one exists (Gmail over MCP), otherwise the controls Windows sees and the keyboard. How it works: - AssemblyAI Universal-Streaming turns speech into text as you talk; pauses merge into one turn. A second backend runs on the Voice Agent API. - Qwen 3.5 4B on AssemblyAI's LLM Gateway plans the steps in under a second (Claude with one line in .env). - Iris Cloud, our server on Oracle Ampere, holds the keys: no keys or GPU needed. Audio goes straight to AssemblyAI; the server stores only usage counts. - A decision model (Jev, or Kev on your GPU) picks each control. Trust: 0 false yeses in 60 spoken answers, 0 risky actions let through in 40 unseen tests. A "no" ends the task. Passwords never reach a model. Accessible by design: "What's on my screen?", "Show me how", "Say that again", sounds for thinking and errors, mute with Ctrl+Alt+M. Business value: free for the person, paid by whoever carries the cost today: families, assistive-tech funders, employers, banks and telcos. The European Accessibility Act applies since June 2025. Team revived, lablab.ai (http://lablab.ai/) x AssemblyAI Voice Agent Hackathon. Open source, MIT.
30 Sep 2026
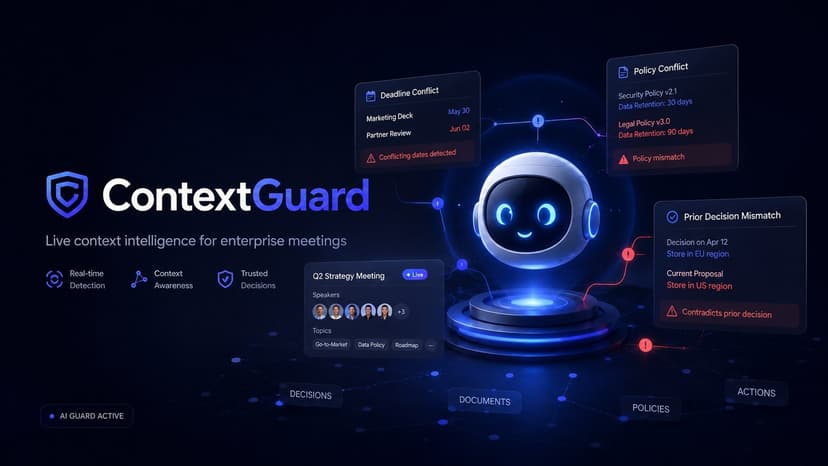
ContextGuard - Live Decision Helper
ContextGuard is a real-time meeting agent that catches conflicts between what's being said and what your company already knows — then acts on it. It listens through Speechmatics with speaker diarization, parses every decision, promise, and assignment via Gemini 2.5 Flash, and checks each one against your company's memory graph: legal blockers, prior decisions, owner capacity, customer commitments, dependency chains. The moment a statement collides with reality, an evidence-backed card appears on screen — citing the exact source ("Legal Review, May 12 — DPA pending") with a suggested next step. The intervention happens during the call, when course-correction still costs seconds. After the meeting, two more layers activate. A Personal Summary engine rewrites the session from one participant's point of view: what they now own, what was decided that affects their scope, which flags involved them. A Service Agent Layer then executes the operational decisions: a GitHub agent updates issues and labels, a Jira/Notion agent reassigns owners and shifts priorities, a Gmail agent drafts the customer email walking back the promise that just got flagged. Every action is logged with before/after diffs. Target audience: product, engineering, and operations teams at companies of 50+ where Sales, Legal, Platform, and Product each carry a different version of reality, and meetings are where those versions collide. The whole stack runs as a single Next.js app, deployable to Vultr in one command — Speechmatics tokens minted server-side, structured Gemini output under a strict JSON schema, and a Valkey-backed action queue so service agents run asynchronously without blocking the meeting UI. Meeting assistants tell you what happened. We surface what would stop it — and then do something about it.
19 May 2026
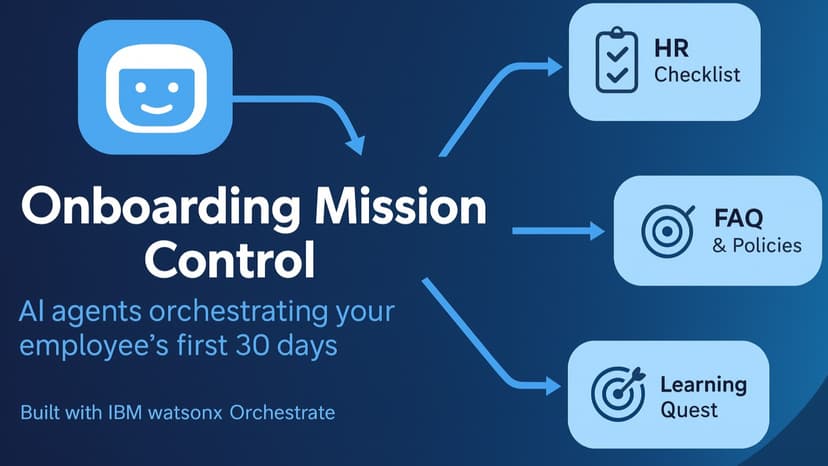
Multi-agent AI cockpit for employee onboarding
Onboarding Mission Control is a multi-agent AI solution that turns fragmented employee onboarding into a guided, trackable journey. Built on IBM watsonx Orchestrate, it uses an orchestration agent to route every request to specialist agents: an HR checklist agent, a role-based Learning Quest agent, a RAG-powered FAQ agent grounded in the employee handbook, and a Knowledge Guardian that reviews RAG answers for hallucinations and policy mismatches. For new hires, the system provides a day-by-day checklist, personalized 3-day learning quests with quizzes and badges, and a conversational FAQ that only responds with verified information. For HR and managers, an agent aggregates progress by user, highlights who is stuck on critical steps such as security or compliance training, and surfaces onboarding risks. The result is faster, more consistent onboarding with less manual follow-up, lower compliance risk, and a reusable orchestration pattern that can be extended to other HR workflows like role changes, promotions and offboarding.
23 Nov 2025


